GLM-5.2 is the new leading open weights model on Artificial Analysis
GLM-5.2: The New Champion of Open Weights Models
Published June 17, 2026 | Source: Artificial Analysis
Z ai has officially released GLM-5.2, which has ascended to the top spot for open weights models on the Artificial Analysis Intelligence Index. With a score of 51, the model now defines the Pareto frontier when balancing Intelligence against Cost per Task.
While GLM-5.2 maintains the same architectural footprint as its predecessor—GLM-5.1 (featuring total parameters and active parameters)—it achieves a massive point increase on the Intelligence Index v4.1. This leap places it significantly ahead of competitors like MiniMax-M3 (44) and DeepSeek V4 Pro (max) (44).
🚀 Key Performance Milestones
Summary:
GLM-5.2is currently the premier open weights model on the Intelligence Index v4.1, outperformingMiniMax-M3,DeepSeek V4 Pro, andKimi K2.6.
Scientific & Reasoning Breakthroughs
The model shows substantial gains across nearly all evaluations, with the most dramatic improvements seen in scientific reasoning:
- CritPt: (reaching )
- HLE: (reaching )
- AA-LCR: (reaching )
- tau3 banking: (reaching )
- SciCode: (reaching )
- TerminalBench v2.1: points (reaching )
- GPQA Diamond: points (reaching )
Agentic Capabilities: GDPval-AA v2
GLM-5.2 dominates the GDPval-AA v2 benchmark, which measures real-world agentic performance.
| Model | GDPval-AA v2 Score |
|---|---|
| GLM-5.2 | 1524 |
| MiniMax-M3 | 1418 |
| DeepSeek V4 Pro (max) | 1328 |
| GPT-5.5 (xhigh reasoning) | 1514 |
Note on GDPval-AA v2 Methodology: This updated benchmark improves upon the original by:
- Baselining Elo to human performance at .
- Implementing a rotating panel of frontier-model judges.
- Extending the turn limit from
100250 to better evaluate long-horizon agent trajectories.
📉 Efficiency and Cost Analysis
The Pareto Frontier
GLM-5.2 occupies a highly strategic position on the Intelligence vs. Cost per Task chart, offering the lowest cost for its specific intelligence tier.
Cost Comparison per Task:
GLM-5.2: ~$0.46GLM-5.1: $0.25Kimi K2.6: $0.31MiniMax-M3: $0.18DeepSeek V4 Pro (max): $0.05
Token Consumption
One trade-off for this intelligence is token efficiency. GLM-5.2 is more "verbose" in its reasoning process:
- Total output tokens per task: (of which is dedicated to reasoning).
- Comparison: This is significantly higher than
GLM-5.1(),MiniMax-M3(),Kimi K2.6(), andDeepSeek V4 Pro().
🛠️ Technical Specifications & Availability
Model Profile
- License: MIT
- Architecture: 744B Total / 40B Active Parameters
- Context Window:
200K1M tokens - Omniscience Index: 4 (Up from 2 in GLM-5.1)
- Accuracy: (vs )
- Hallucination Rate: (vs )
- Attempt Rate: (Flat)
Pricing Structure
The pricing remains consistent with the previous version:
{
  "pricing_per_1M_tokens": {
    "input": "$1.40",
    "output": "$4.40",
    "cache_hit": "$0.26"
  }
}
Where to Access
Beyond Z ai's own API, GLM-5.2 is available via:
- DeepInfra
- Novita
- Nebius
- Parasail
- Siliconflow
- GMI Cloud
- Baseten
- Fireworks
🖼️ Visual Data & Analysis
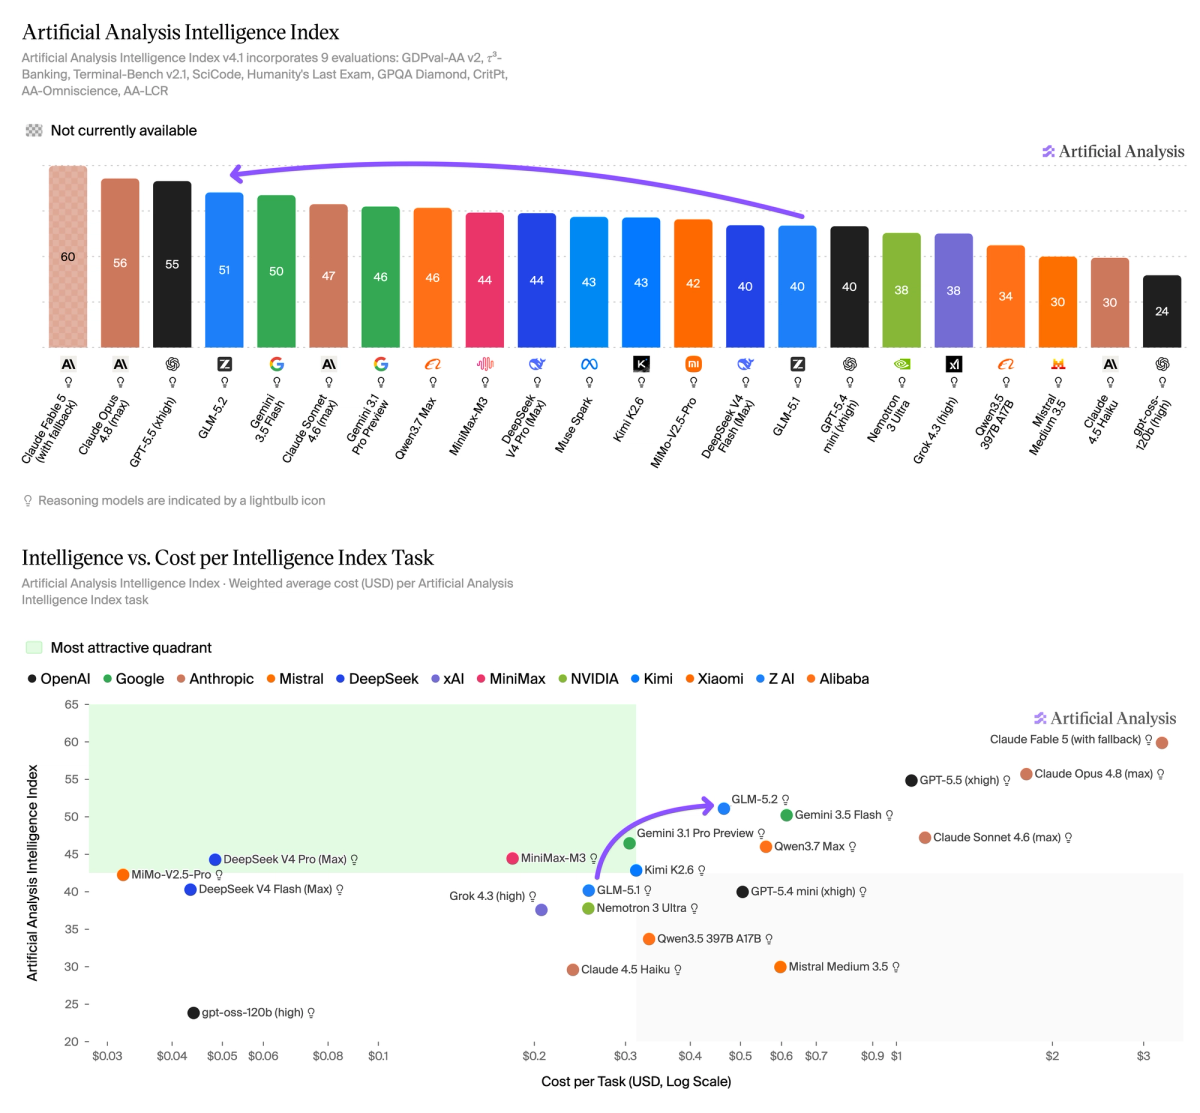 Figure 1: Intelligence Index Positioning
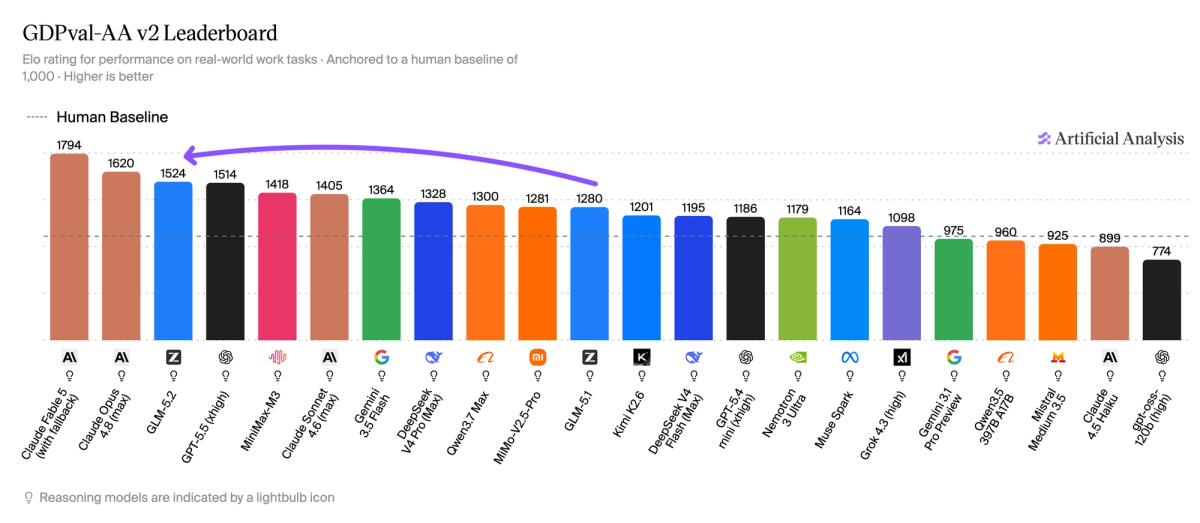 Figure 2: Cost vs. Intelligence Pareto Frontier
 Figure 3: Detailed Evaluation Breakdown
 Figure 4: Token Efficiency Analysis
 Figure 5: Agentic Performance Metrics
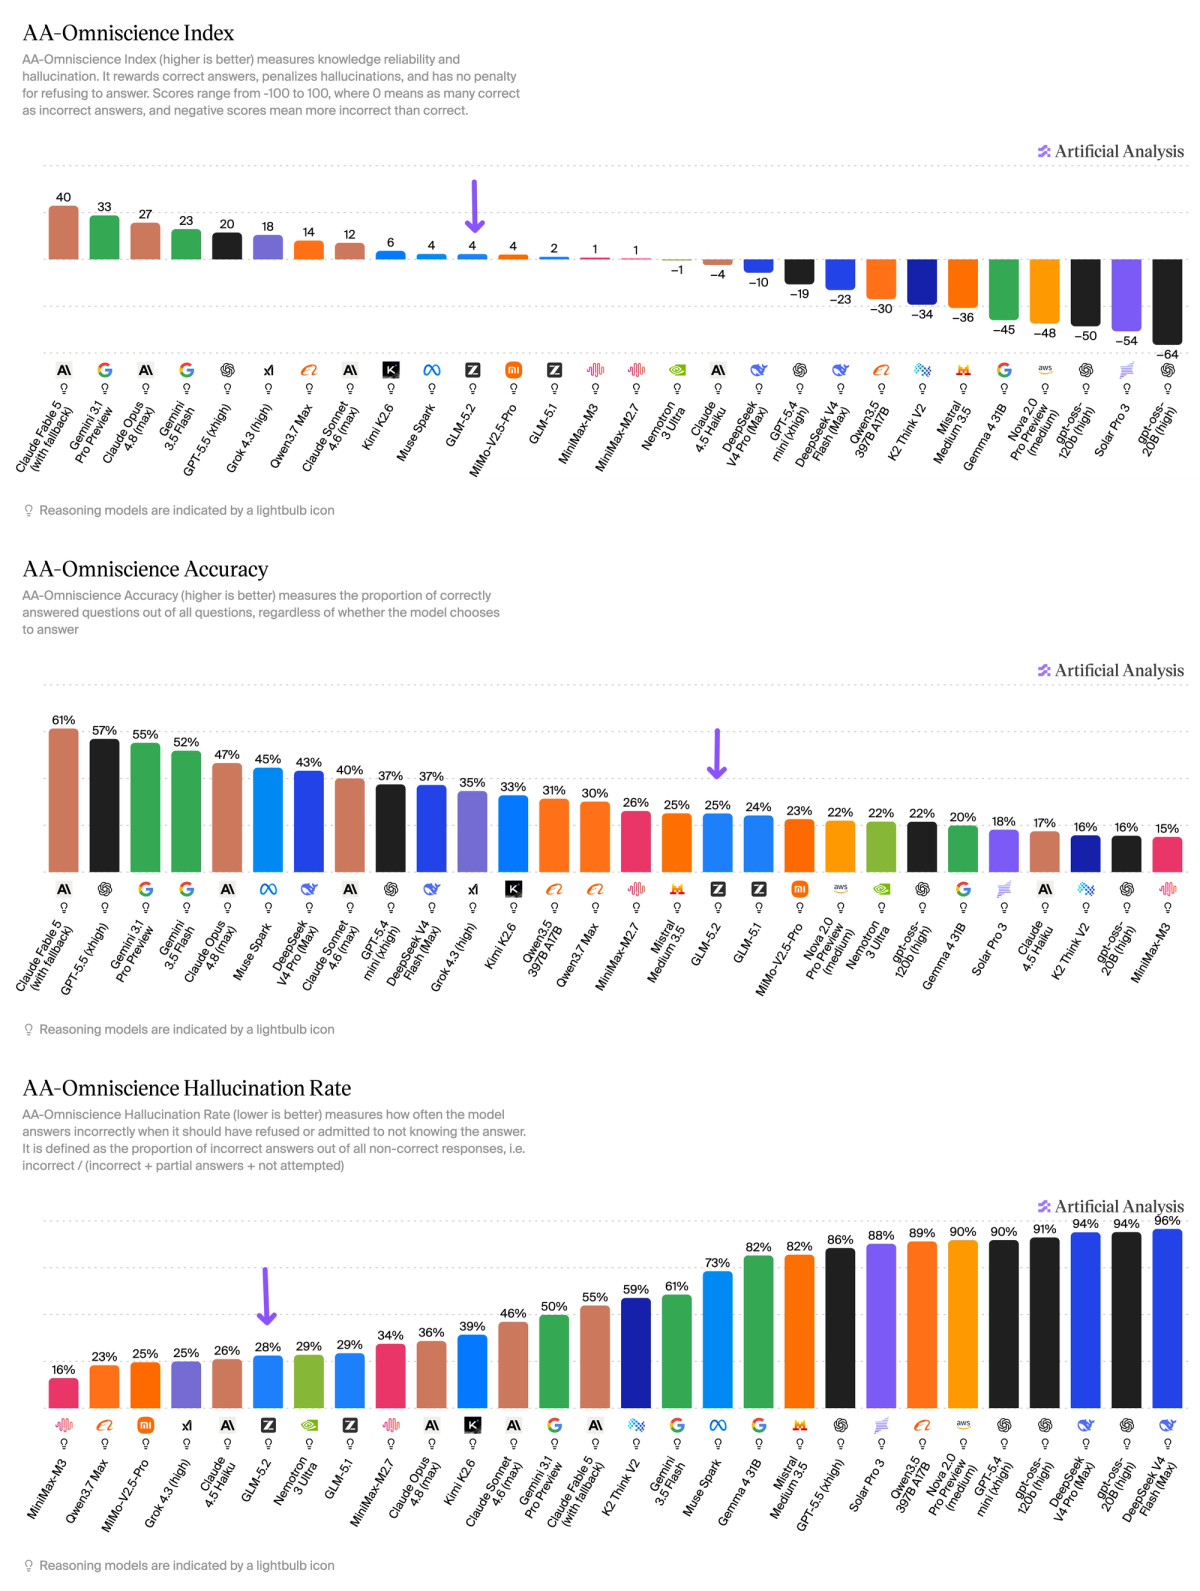 Figure 6: Comparison with Proprietary Models
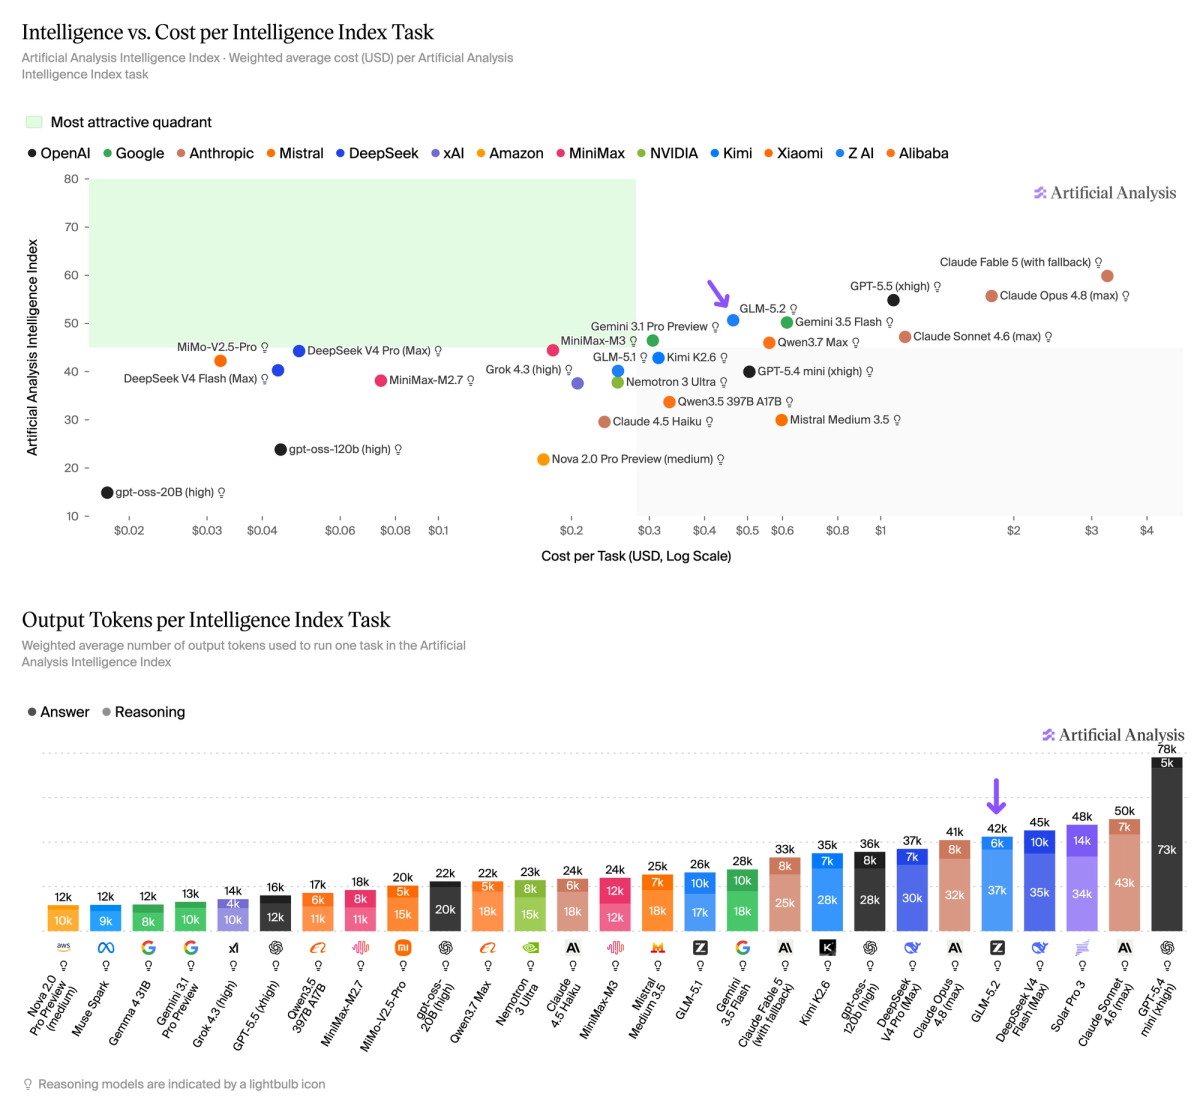 Figure 7: Intelligence Index v4.1 Distribution
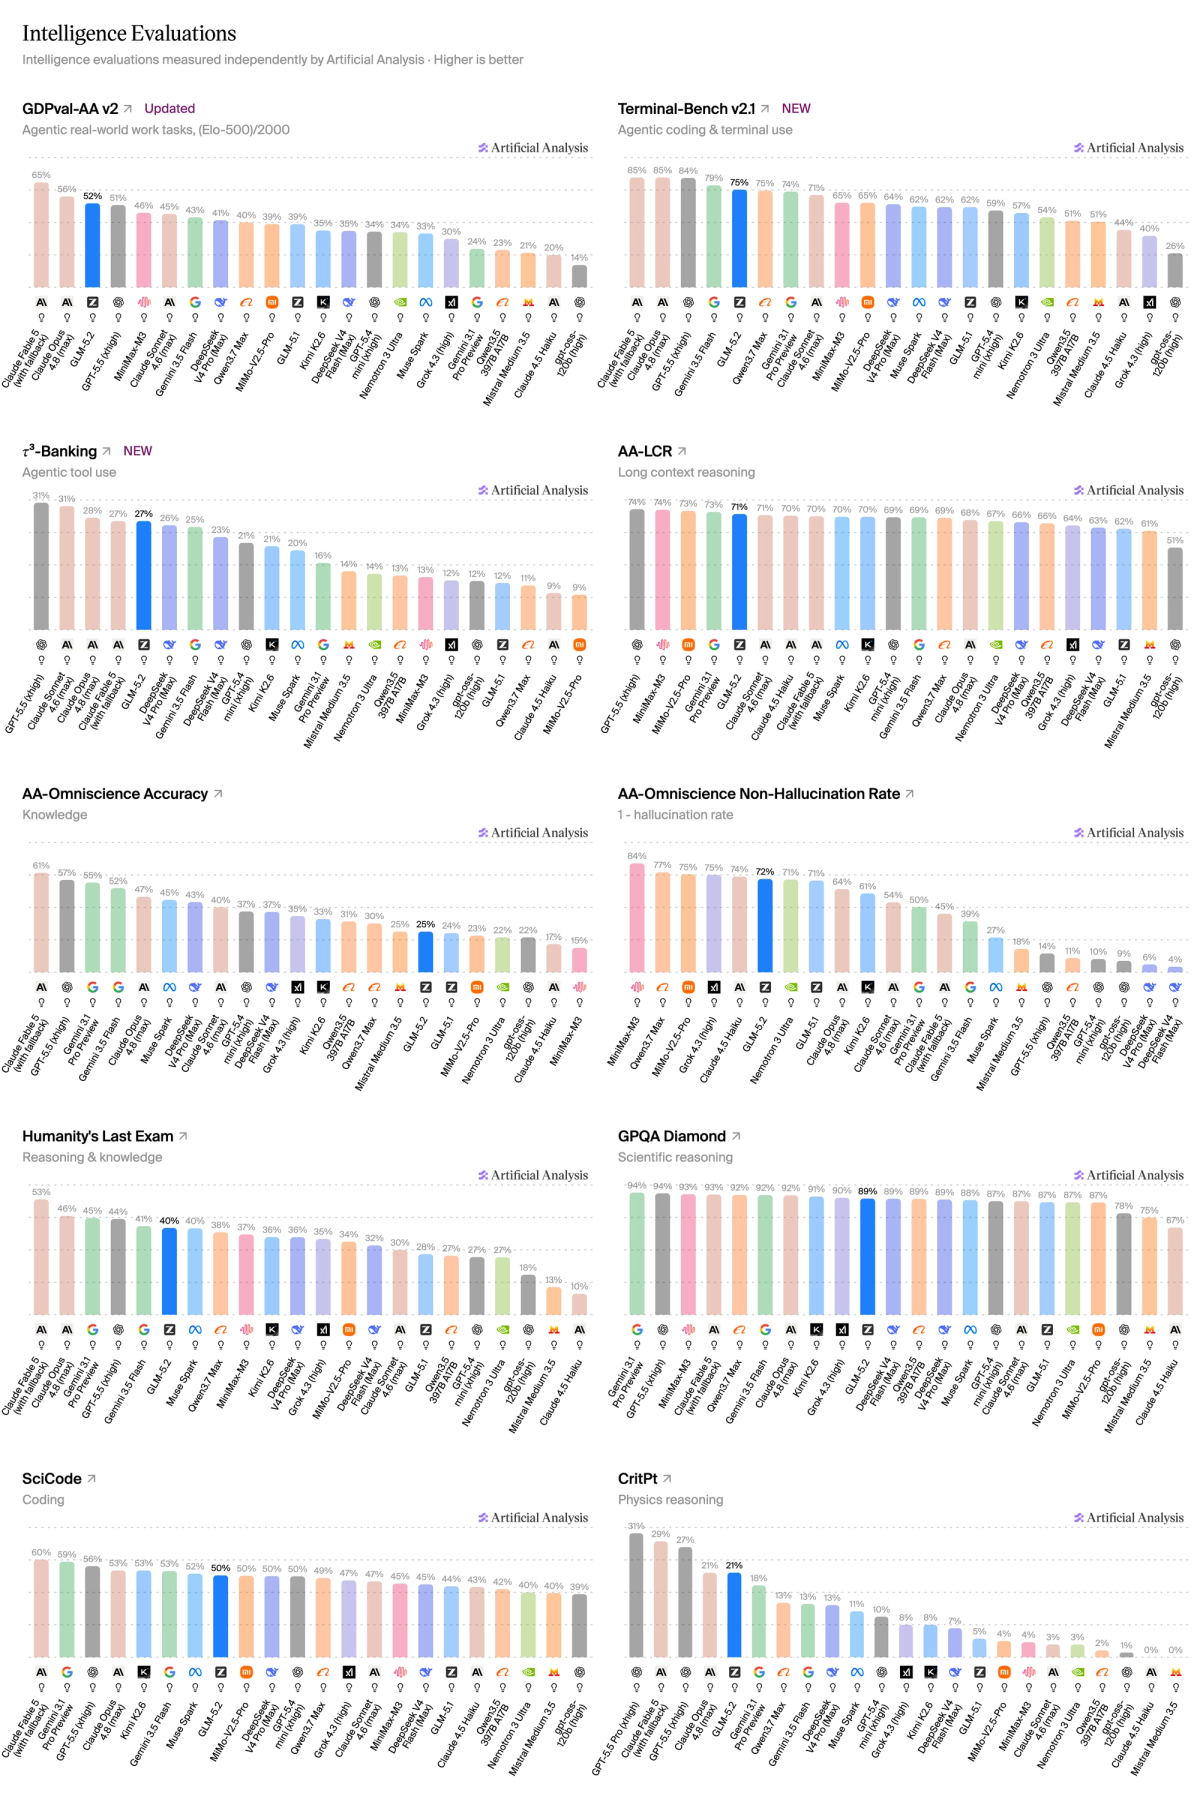 Figure 8: Reasoning Token Breakdown

Further Reading:
- Explore
GLM-5.2at artificialanalysis.ai/models/glm-5-2 - Read about the shift toward agentic workloads in the Intelligence Index v4.1 announcement (June 16, 2026).
- Check out the launch of Claude Fable 5, the first Mythos-class model (June 10, 2026).