Postgres data stored in Parquet on S3: LTAP architecture explained
Postgres data stored in Parquet on S3: LTAP architecture explained
By Reynold Xin | Engineering | June 30, 2026
Executive Summary
The traditional database model—where the write-ahead log and data files reside on a single machine's disk—is the primary culprit behind several systemic issues: the risk of data loss, the exorbitant cost of high-availability (HA) clones and read replicas, and the tendency for analytical queries to cripple transactional performance.
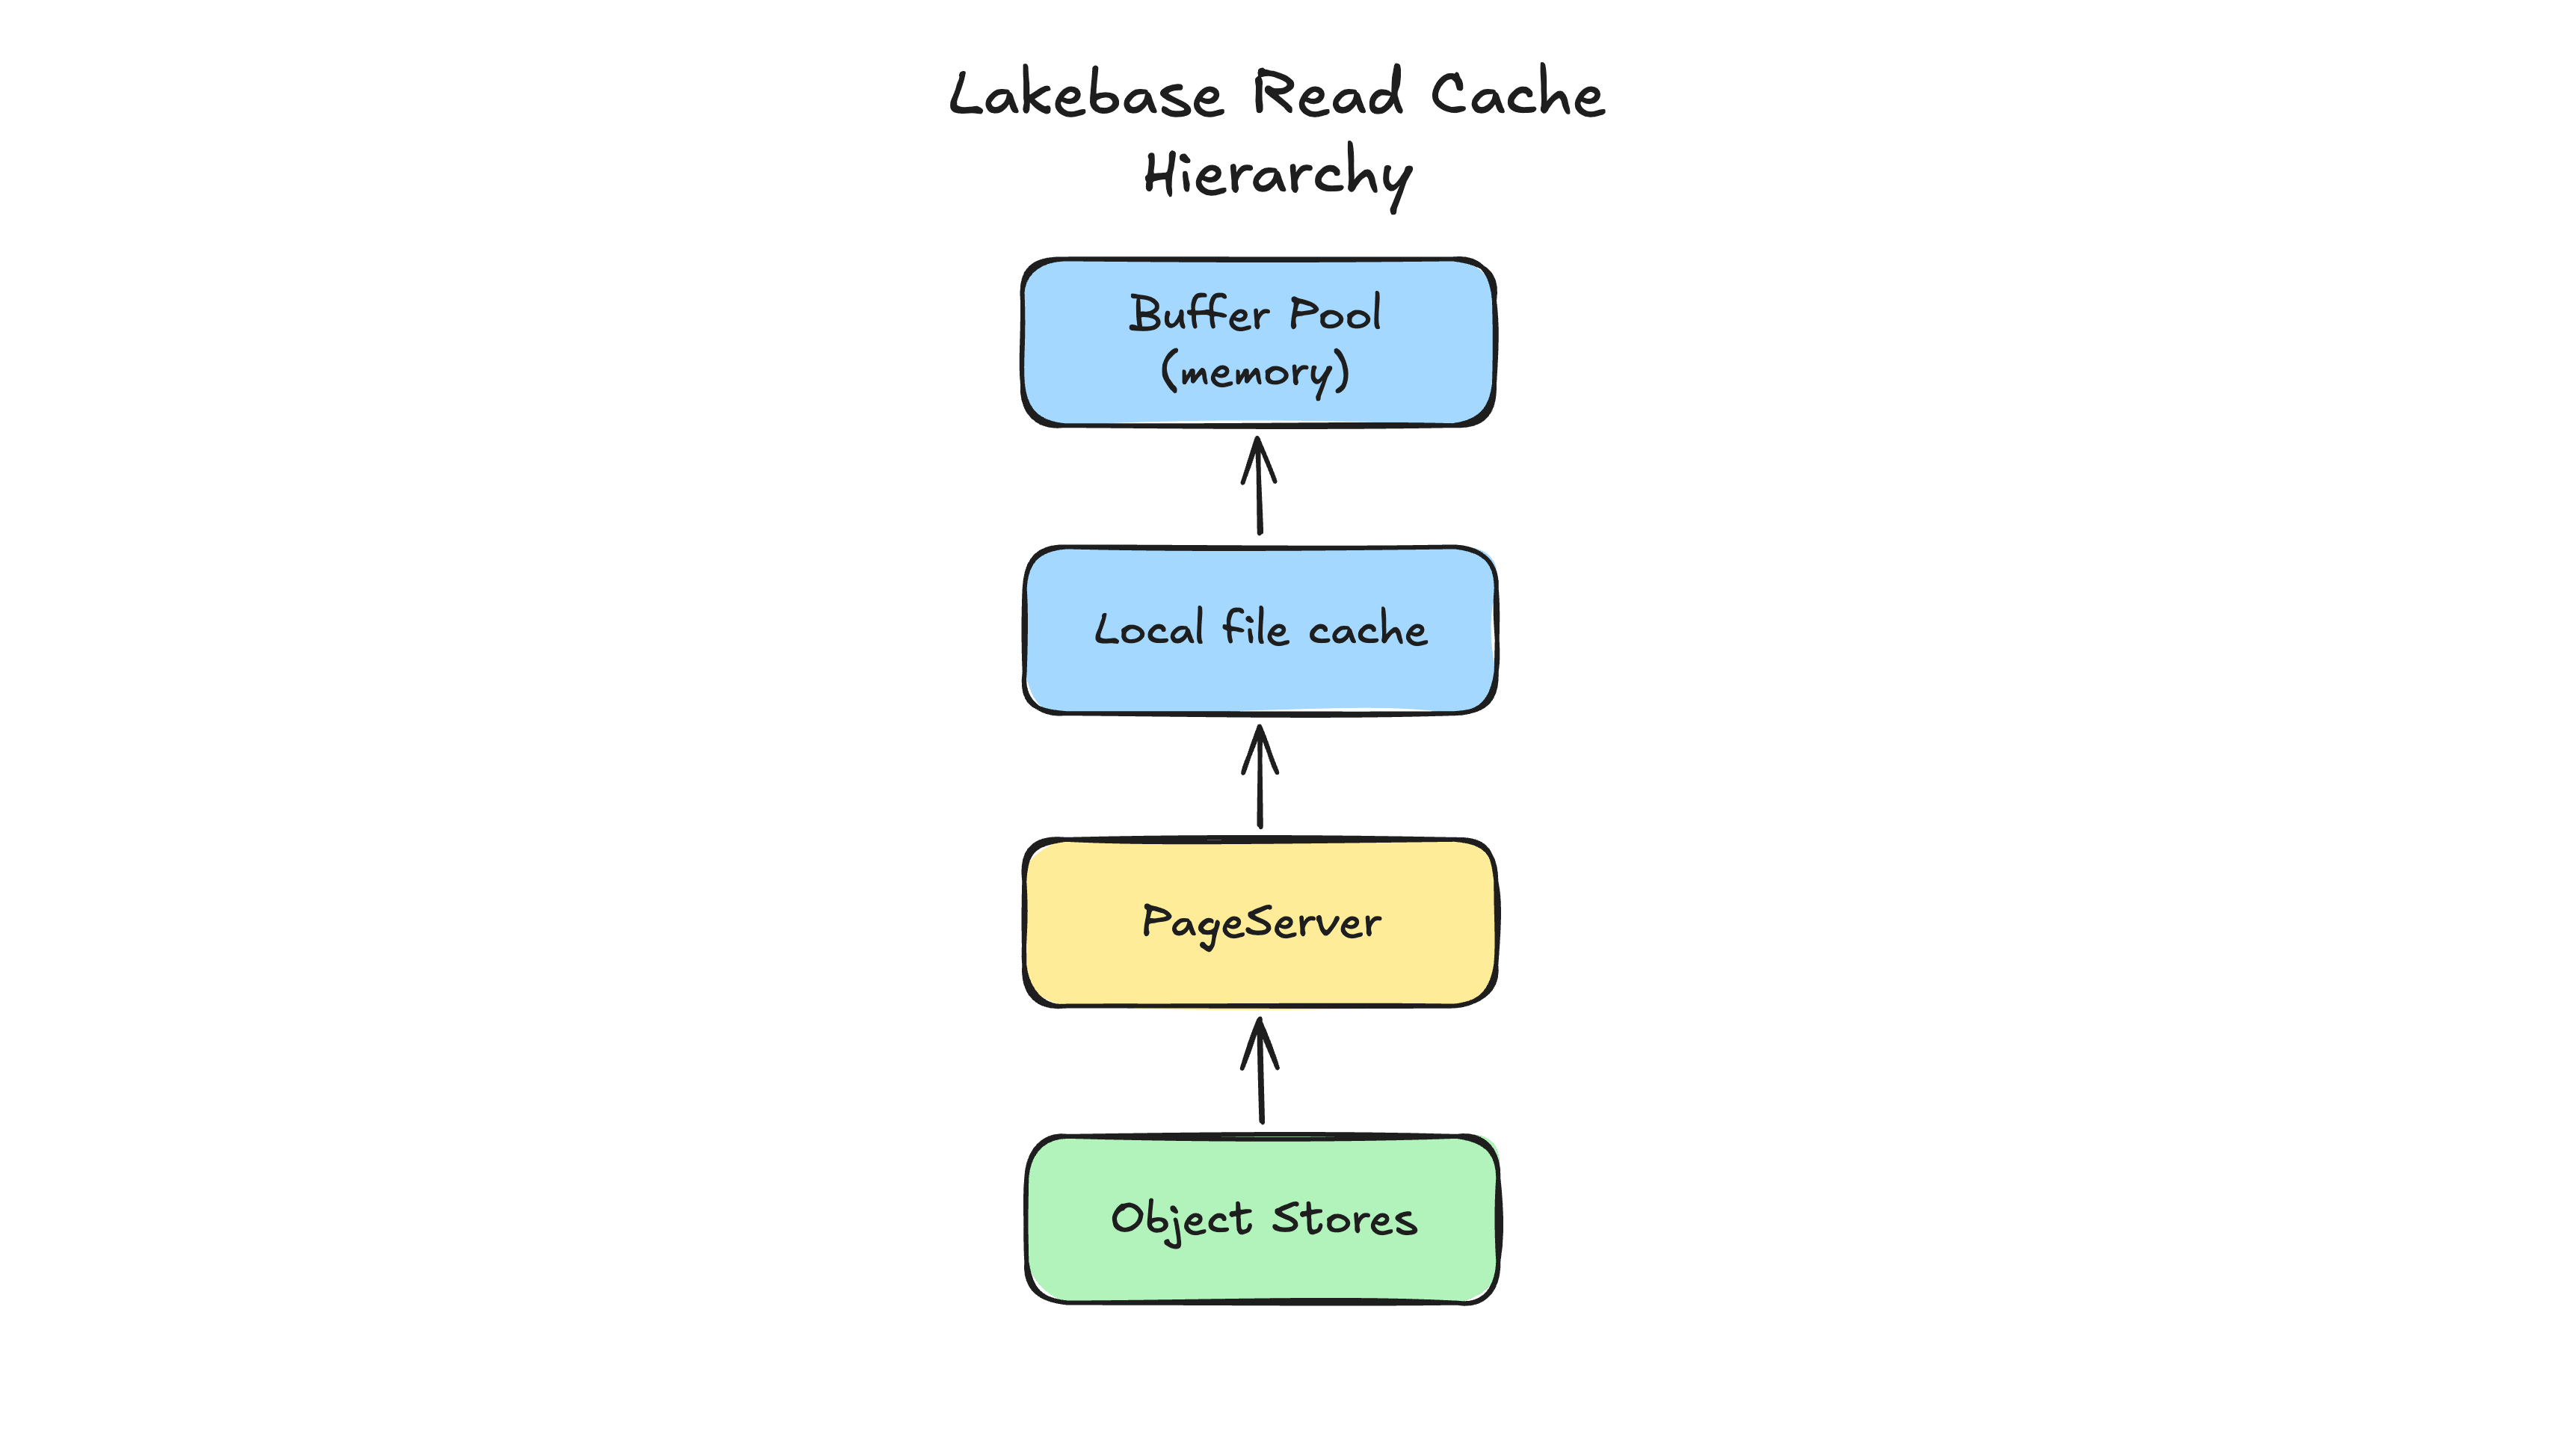
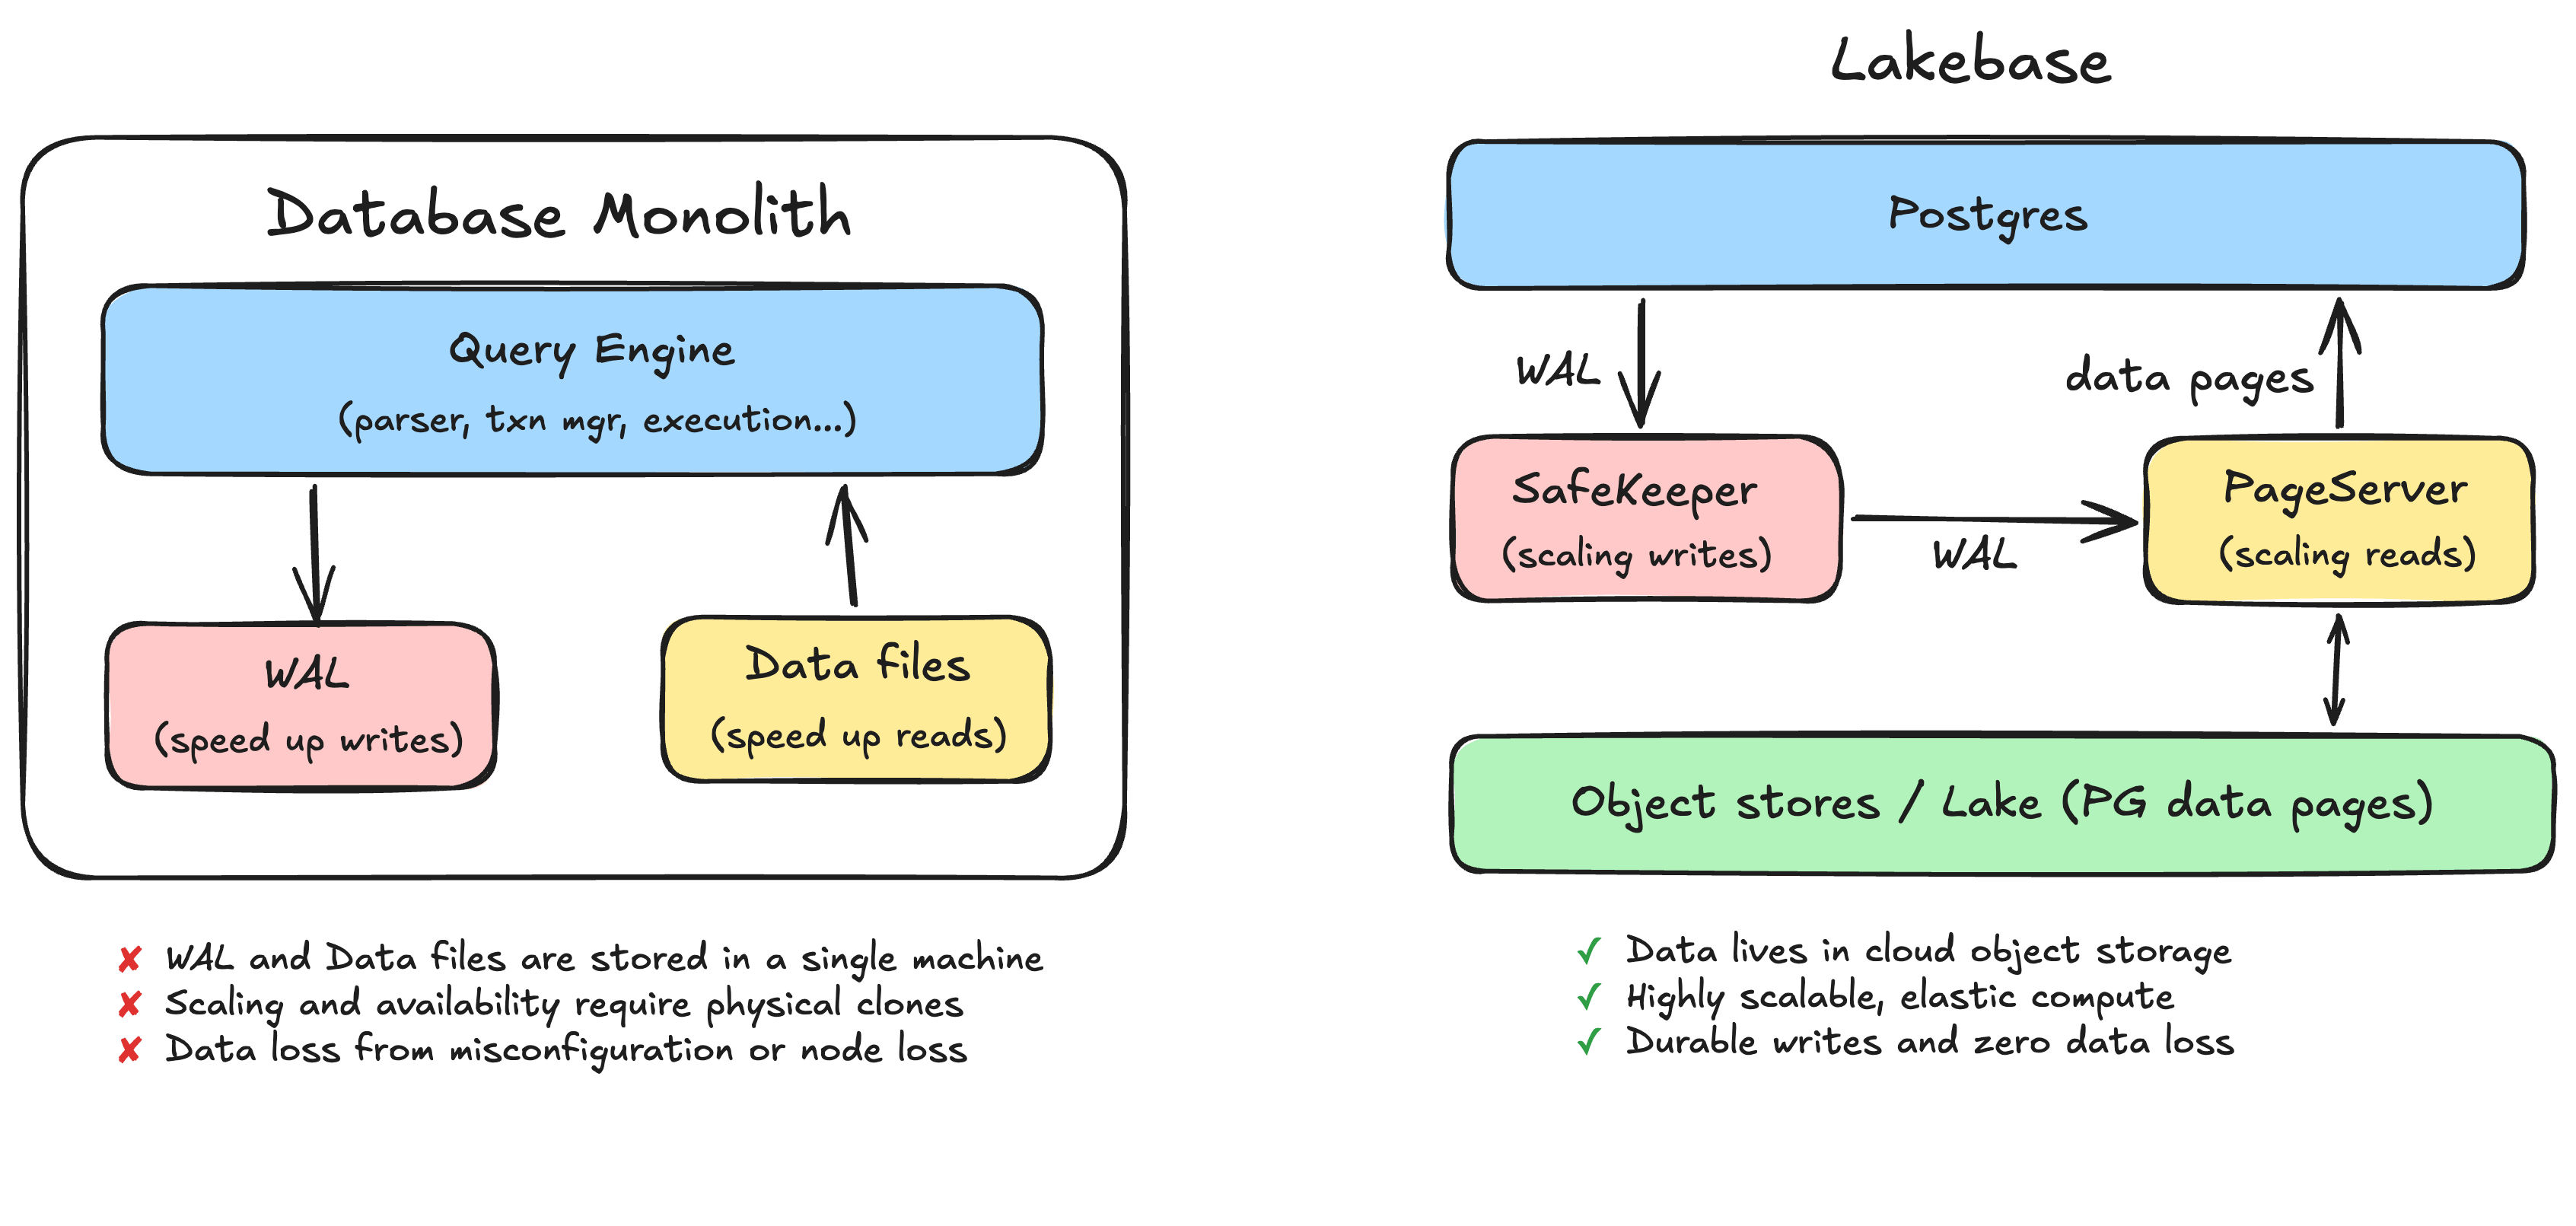
Lakebase solves this by rendering Postgres compute stateless. It achieves this by offloading the log and data files to specialized cloud services: SafeKeeper and PageServer. This transition enables:
- (Unlimited) storage capacity.
- Elastic compute scaling.
- Highly durable writes and simplified HA.
- Instantaneous branching without significant latency.
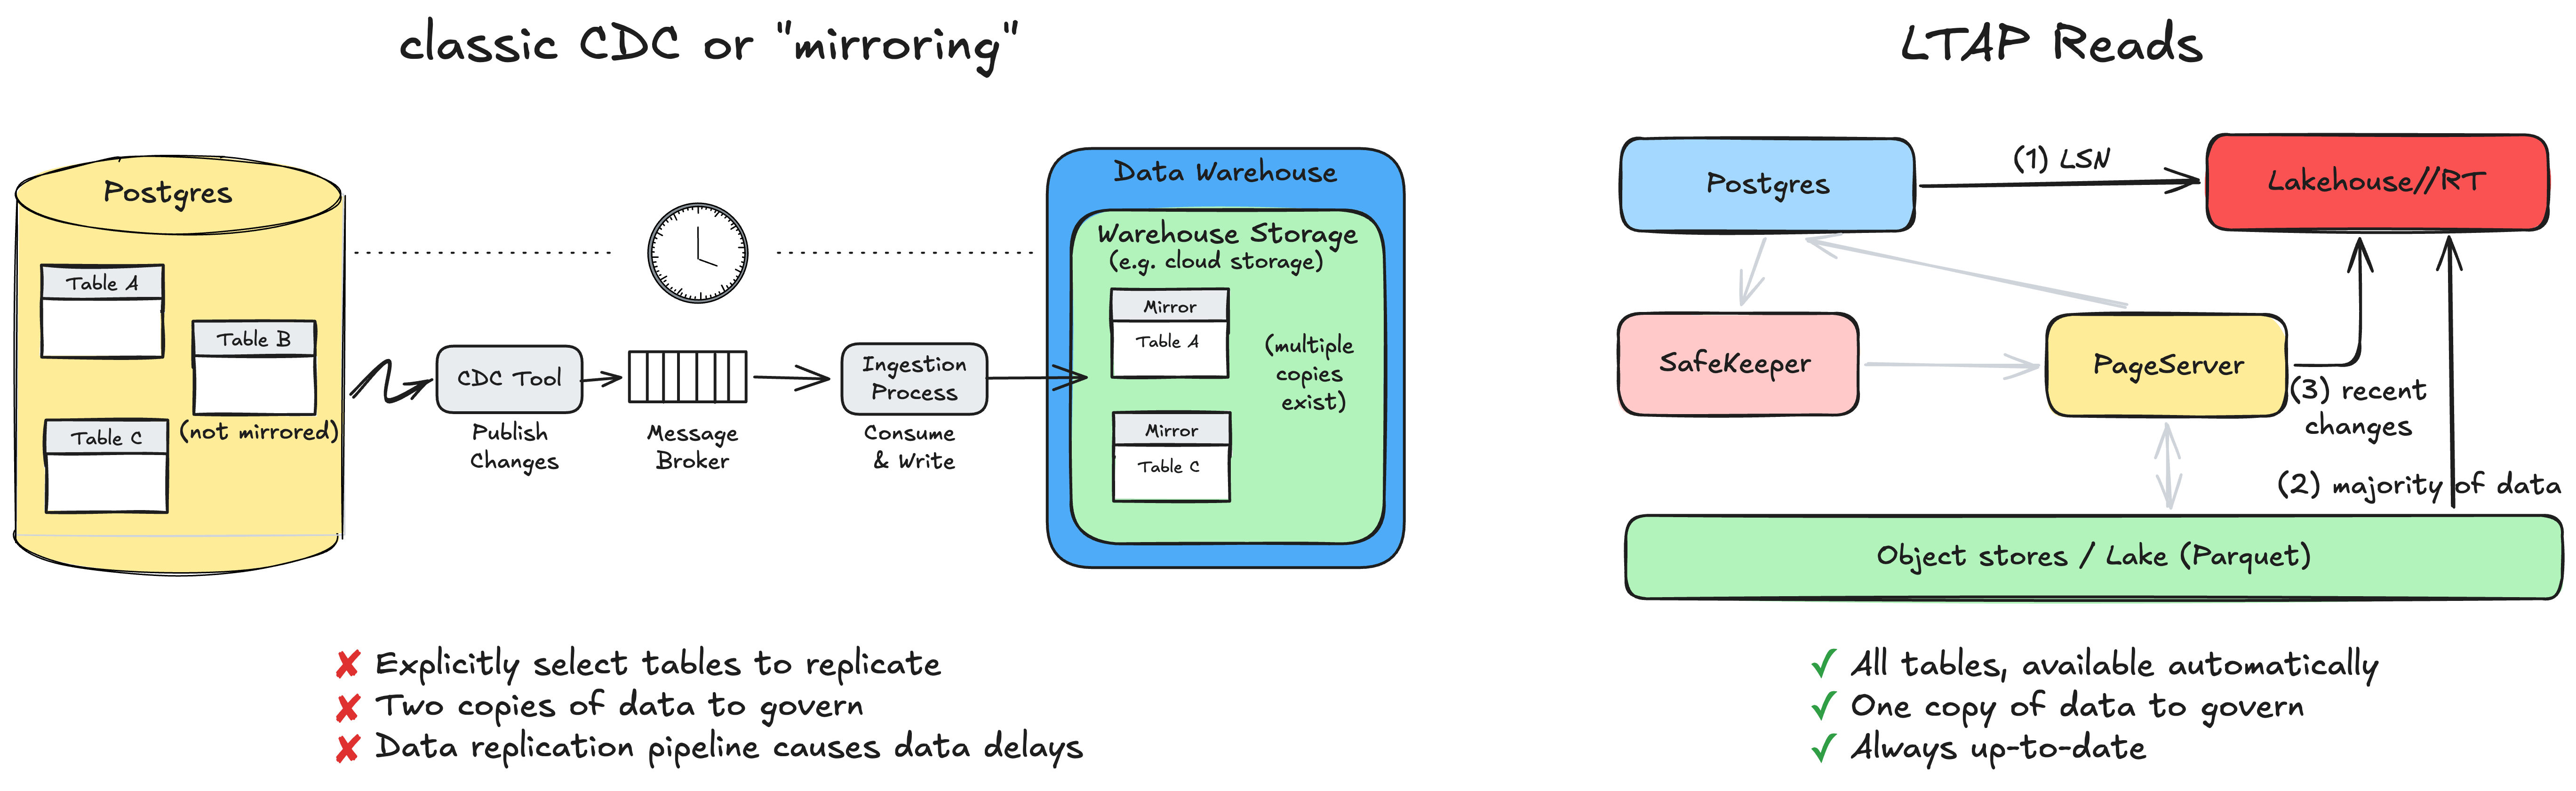
LTAP (Lakehouse Transactional Analytical Processing) takes this a step further. By storing operational data in open columnar formats, both Postgres and Lakehouse engines can access the same fresh data. This eliminates the need for CDC pipelines or maintaining duplicate copies, ensuring analytics don't slow down transactions.
Crucial Distinction: While HTAP attempts to merge both workloads into a single engine, LTAP unifies them at the storage layer, allowing the most efficient engine to handle each specific task.
The Journey to Lakebase
About 16 years ago, during my PhD at UC Berkeley, I was told:
"OLTP databases are a solved problem."
At the time, we were just beginning to harness massive amounts of structured and unstructured data to fuel what we now call "AI." Following that advice, I helped launch the research project that evolved into Apache Spark and, subsequently, Databricks.
However, as we integrated various databases into our ecosystem, it became clear that OLTP databases were solved far from solved. They were fragile, clunky, and notoriously difficult to scale. This frustration led us to a fundamental question: If we designed an OLTP database from scratch today, what would it look like?
The answer to that question is Lakebase, our serverless Postgres implementation.
Understanding the "Database as a Monolith"
Most modern databases, including Postgres (which also has Berkeley roots), operate as monoliths. In this setup, a single machine handles both the database engine and the physical storage.
The Two Pillars of Disk Storage
In a monolithic system, two components are critical:
- The Write-Ahead Log (WAL): A sequential record of all changes.
- The Data Files: The actual state of the database.
When a transaction is committed, the system doesn't immediately update the data files because random I/O is too slow. Instead, it appends the change to the WAL.
The Logic: The WAL ensures writes are fast and safe; the data files ensure reads are fast by avoiding the need to replay the entire history of the database.
[!WARNING] For those seeking the granular details of this architecture, I recommend the ARIES paper. It is 69 pages long and is widely considered one of the most complex documents in computer science.
The Cost of Monolithic Design
Because this architecture is the industry standard, it introduces several critical failure points:
1. The Durability Gap
Data loss often stems from misconfiguration. If the OS or storage layer acknowledges a WAL write before it is actually flushed to permanent media, a kernel panic or power failure can erase committed transactions.
# Example of a risky configuration where the OS might "lie" about flushing
fsync = off
2. The Scaling Tax
When a single node can't handle the load, the typical solution is a read replica. However, this is inefficient:
- Physical Copies: A replica is a full copy of the entire dataset.
- Slow Provisioning: Copying massive datasets and replaying logs takes significant time.
- Infrastructure Cost: To ensure HA, you often need nodes, effectively tripling your hardware spend.
3. Resource Contention
Analytical queries (OLAP) and transactional queries (OLTP) fight for the same CPU and RAM. A single massive GDPR cleanup or a complex report can spike latency for every user on the system.
Monolith Failure Checklist
- Risk of silent data loss via OS caching.
- High cost of redundant physical copies.
- Slow recovery/provisioning times.
- Performance degradation during heavy reporting.
Comparing Architectures
| Feature | Monolithic Postgres | Lakebase (Stateless) | LTAP (Lakehouse) |
|---|---|---|---|
| Storage | Local Disk (Coupled) | Externalized Services | Open Columnar (S3/Parquet) |
| Compute | Fixed/Coupled | Elastic/Stateless | Specialized Engines |
| Data Copies | Multiple (Replicas) | Single Source of Truth | Single Source of Truth |
| Analytics | Contends with OLTP | Separate Replica | Direct read from storage |
| Pipeline | CDC Warehouse | CDC Warehouse | No CDC Required |
Moving Toward LTAP
By externalizing the storage, Lakebase removes the fragility of the monolith. But LTAP goes further by changing the format of that storage.
Instead of proprietary data files, LTAP uses open columnar formats (like Parquet) on S3. This allows:
- Postgres to handle the high-concurrency transactional writes.
- Lakehouse Engines to run massive analytical queries on that same data in real-time.
Visualizing the Shift
Traditional CDC Flow:
The Lakebase Hierarchy:
Monolith Structure:
By unifying at the storage layer, we eliminate the "second copy" problem and the lag associated with Change Data Capture (CDC), creating a system where transactions and analytics coexist without compromise.