Today I Rescued 7,234 Old GIFs
Saving a Piece of Web History: The Rescue of 7,234 GIFs
Recently, a user named GlitchyZorua alerted me to the Ibiblio Icon Browser, a massive treasury of GIF icons meticulously gathered by Gioacchino La Vecchia during the 1990s.
Glitchy’s mission was simple: create a full archive of these icons. However, the execution proved to be surprisingly difficult.
The Architecture of the Archive
On the surface, the site's organization seems straightforward. The navigation flow follows this path:
Most of these icons are pixels, but the real problem arises when attempting to move from a directory page to an actual image file.
The Technical Hurdle: Server-Side Imagemaps
While it looks like you are clicking a standard hyperlink, you are actually interacting with an imagemap.
What is an imagemap? It is a way to define specific clickable regions within a single image that lead to different destinations.
There are two primary types:
- Client-side: The HTML contains all the coordinates and the final URLs.
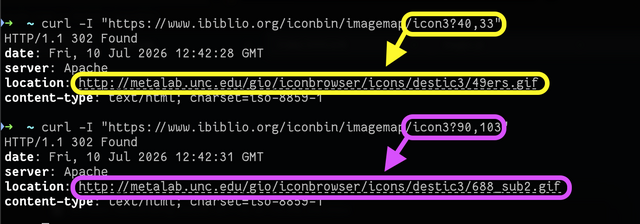
- Server-side: The browser sends the exact pixel coordinates of the click to the server as a query string, and the server decides where to redirect the user.
The Ibiblio site uses the latter. The HTML looks like this:
<a href="/iconbin/imagemap/icon3" img src="destic3/icons.gif" ismap />
The ismap attribute is the key; it tells the browser to transmit the coordinates. Because directory indexing is disabled, manually guessing the filenames or inspecting the source code provides no direct URLs to the GIF library.
Reverse Engineering the Grid
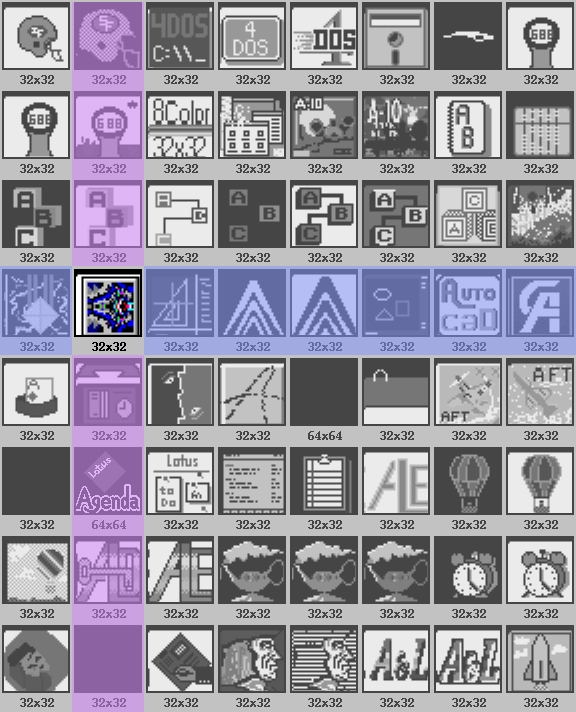
Since archive.org also failed to capture the full set, I decided to find a programmatic solution. By analyzing the gallery images, I discovered they are arranged in a grid (up to ). Each cell, including its label, occupies a space of pixels.
I suspected the server (likely running Apache with mod_imagemaps) used a configuration file similar to this:
| Icon Filename | Top Left (X,Y) | Bottom Right (X,Y) |
|---|---|---|
49ers.gif | ||
49ers1.gif | ||
4dos.2.gif | ||
4dos.gif |
I truly hope La Vecchia used a script to generate these thousands of lines of config rather than typing them by hand!
The Recovery Process
Since we know each hit area is pixels, we can target the center of the first cell at and then increment by 72 and 89 pixels to find every other center point.
My rescue checklist:
- Iterate through libraries 1 to 113.
- Permute X coordinates: .
- Permute Y coordinates: .
- Send
HTTP HEADrequests to the resulting URLs. - Capture the
Location:header fromHTTP 302redirects.
In pseudocode, the logic looked like this:
# Pseudocode for GIF extraction
libraries.each do |lib|
  x_coords.each do |x|
    y_coords.each do |y|
      url = "https://www.ibiblio.org/iconbin/imagemap/icon#{lib}?#{x},#{y}"
      response = make_head_request(url)
      save_url(response.location) if response.code == 302
    end
  end
end
The Result: A Modernized Gallery
Once the URLs were harvested, I didn't just want a folder of images; I wanted a usable site. I built a basic static site generator using Ruby and ERB templates.
The new version features:
- Pagination (preserving the original page structure).
- Client-side search functionality.
- A cloneable repository for those who want the raw files.
You can explore the rescued collection at: ibiblio-icon-archive.danq.dev. It still feels like a relic of the past, but it is now accessible and preserved.
Community Discussion
Spencer: It's funny that they used a pixel map for images. That's a huge size increase! I remember the pain of 56k modems. Was reducing server requests more important than total page size? Also, what about the licenses?
Dan Q: Some images were larger than , and using composite images allowed them to share a color table, saving some space. However, the main benefit was avoiding the overhead of HTTP 1.x. Back then, every single image required a new TCP handshake and IP connection. One large image loads much faster than 64 tiny ones. Regarding licenses, I'm contacting the owner, but these were likely shared under the "fair use" culture of the early web.
Contributors: