Kimi K3, and what we can still learn from the pelican benchmark
Kimi K3: Insights from the "Pelican Benchmark"
On July 16, 2026, the Chinese AI research lab Moonshot AI unveiled Kimi K3. They've positioned it as their most powerful model to date, boasting a massive scale of 2.8 trillion parameters.
While the model is already live via API and their web interface, Moonshot has committed to an open-weight release by July 27, 2026 (scheduled for July 27, 2026).
The "3T-Class" Contender
Moonshot is marketing K3 as the first "open 3T-class model"—essentially rounding 2.8 trillion up to 3 trillion—which allows it to surpass DeepSeek’s v4 Pro (1.6T) in sheer size.
Performance Benchmarks
According to self-reported data, K3's standing is as follows:
- Wins against: GPT-5.5 high and Claude Opus 4.8 max.
- Loses to: GPT-5.6 Sol and Claude Fable 5.
An Artificial Analysis report provided deeper granularity:
| Metric | Kimi K3 Value | Comparison/Note |
|---|---|---|
| Long-horizon Elo | 1547 | +732 over K2.6; only behind Claude Fable 5 |
| Cost per Task | $0.94 | Similar to GPT-5.6 Sol (1.80) |
| Token Efficiency | Used 21% fewer output tokens than K2.6 | |
| Frontend Code | #1 | Currently leads the Arena.ai Frontend Code arena |
The Cost of Power
Kimi K3 introduces a new pricing tier: 15 per million output tokens. This aligns it with Anthropic’s Claude Sonnet series and marks it as the most expensive offering from a Chinese AI lab so far. This is a steep climb from Kimi K2.6, which cost only 4.
Note: The jump in price correlates with the jump in scale; 2.8T parameters is more than double the size of the previous 1T model.
The Pelican Experiment
To test the model, I used the llm-openrouter plugin via OpenRouter to avoid the hassle of a new API key. I ran the following command:
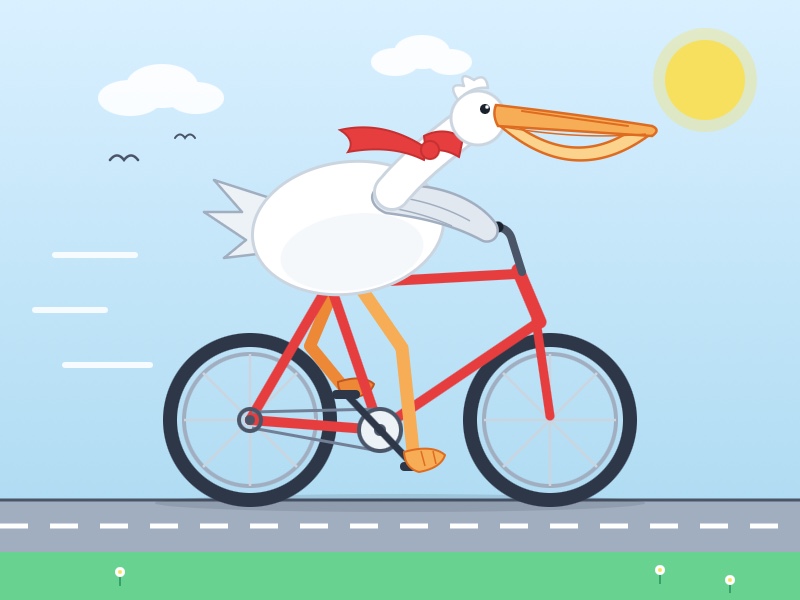
llm -m openrouter/moonshotai/kimi-k3 'Generate an SVG of a pelican riding a bicycle'
The Results
The model generated an SVG image. The resource consumption was:
- Input: 95 tokens
- Output: 16,658 tokens (of which 13,241 were reasoning tokens)
- Total Cost: $0.25
Because K3 is multimodal, I fed the resulting SVG back into the model with an alt-text prompt. For a mere 0.6 cents, it accurately described the image: "Cartoon illustration of a white pelican wearing a red scarf, riding a red bicycle along a gray road... background shows a light blue sky with white clouds, a yellow sun..."
The Workflow Logic
What the "Pelican Benchmark" Actually Teaches Us
This specific test—a pelican on a bike—is now 21 months old. It began as a joke about the difficulty of model comparison, but for the first year, it surprisingly correlated with actual model quality.
Current Observations:
- GLM-5.2 produces better pelicans than GPT-5.6 or Claude Fable 5, though I don't consider GLM to be in the "Fable-class" of intelligence.
- I suspect labs aren't specifically training for this benchmark (otherwise, results would be perfect), though Gemini might have optimized for "animals on vehicles."
Limitations and Value
The pelican test cannot measure agentic tool calling or reliability in long-form conversations—the most critical features for modern AI. However, it remains useful for several reasons:
- Forcing Function: It proves I actually got the model running.
- Deployment Test: It tests my pipeline (API OpenRouter
llama.cpp/Ollama/LM Studio LLM CLI). - Baseline Metrics: It provides a "Hello World" for cost and reasoning estimates.
- Spatial Awareness: It confirms the model understands basic geometry and valid SVG syntax (especially vital for local, smaller models).
- Tradition: It's a Hacker News staple; if I post without a pelican, the community asks where it is!
Technical Nuances of K3
Running this simple prompt revealed a few quirks about Kimi K3:
- Reasoning Effort: Currently, it only offers a "max" setting. This is evident in the token ratio:
- Hidden Prompts: The tokenization is unusual. While OpenAI or Anthropic might count the pelican prompt as 10–30 tokens, K3 counted 95. Even a simple "hi" cost 86 tokens, suggesting a hidden system prompt of approximately 85 tokens.