Towards a Theory of Bugs: The Ruliology of the Unexpected
Towards a Theory of Bugs: The Ruliology of the Unexpected
“My Program Did the Wrong Thing!”
Software bugs are an inescapable part of the digital landscape. By their very nature, they are predictable unique and surprising. Given how frequently they occur, it is reasonable to ask: Is there a formal, scientific framework we can use to understand them?
As it turns out, we can analyze bugs through the lens of ruliology, specifically by applying the concepts of computational reducibility and computational irreducibility. By doing so, we can uncover the fundamental tension between how effectively a program computes and how likely it is to contain errors.
The Core Philosophy of Bugs
When we develop software, we typically hold a mental image of the desired outcome. For this image to fit within human cognition, it must be computationally simple. However, the actual execution of the code may not be.
The Gap Between Expectation and Reality
The Principle of Computational Equivalence suggests that even programs with incredibly simple rules can engage in computation as sophisticated as any other system. This leads to a critical divide:
- Computational Reducibility: The program behaves exactly as our simple mental model predicts.
- Computational Irreducibility: The program performs operations that cannot be shortcut or predicted without actually running the computation.
When a program enters a state of irreducibility, it may perform actions that we didn't foresee. We perceive these unforeseen actions as bugs.
Can AI Solve This?
While AI and automated verification tools can identify bugs within "pockets of computational reducibility," they cannot bypass the fundamental nature of irreducibility. If a process is truly irreducible, nothing short of running the code for that specific case will reveal the outcome.
Case Study: Bugs in Turing Machines
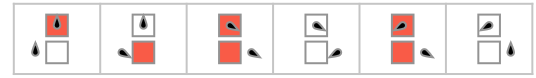
To illustrate this, let's examine a basic (3-state, 2-color) Turing machine. Suppose we provide the machine with a binary integer and observe the output when the head moves past its starting position.
The Illusion of Correctness
At first glance, the machine appears to be performing a simple addition:
| Input () | Expected Output | Actual Output | Status |
|---|---|---|---|
| 1 | 2 | 2 | ✅ |
| 2 | 3 | 3 | ✅ |
| 3 | 4 | 4 | ✅ |
| 4 | 5 | 5 | ✅ |
| 5 | 6 | 6 | ✅ |
| 6 | 7 | 7 | ✅ |
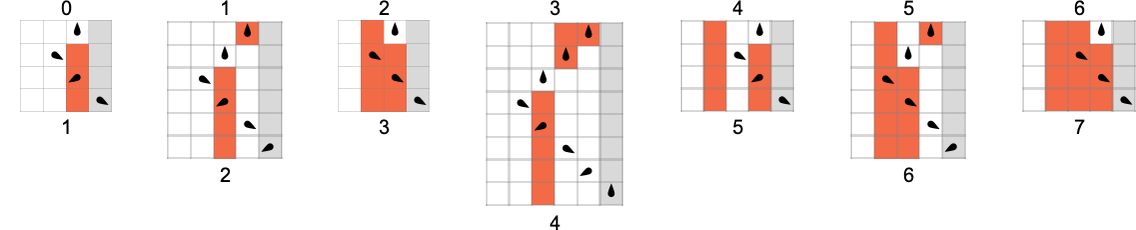
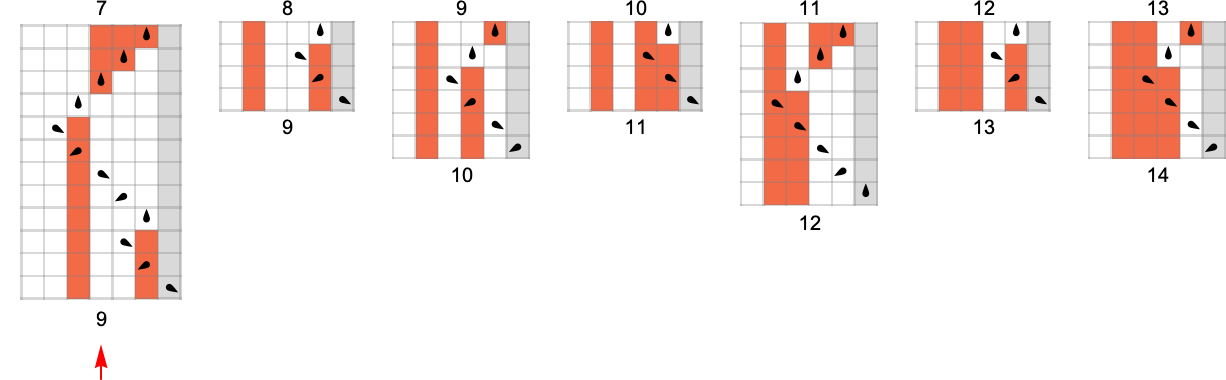
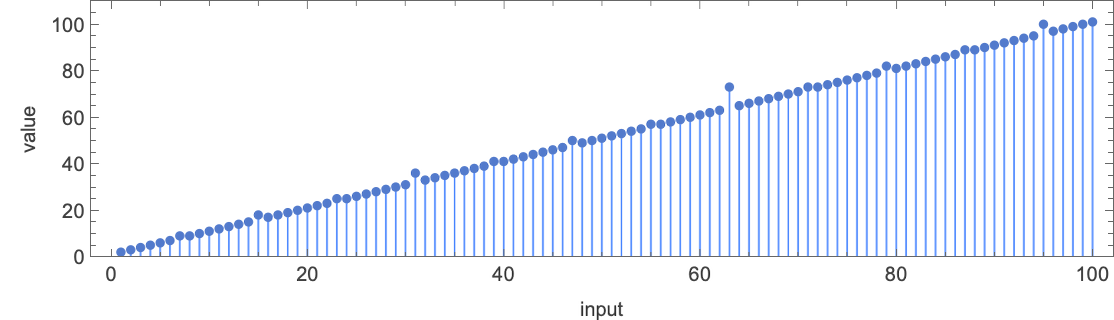
| 7 | 8 | 9 | ❌ BUG! |
For the first few cases, we assume the rule is simply . However, at , the system fails.
Analyzing the "Glitch"
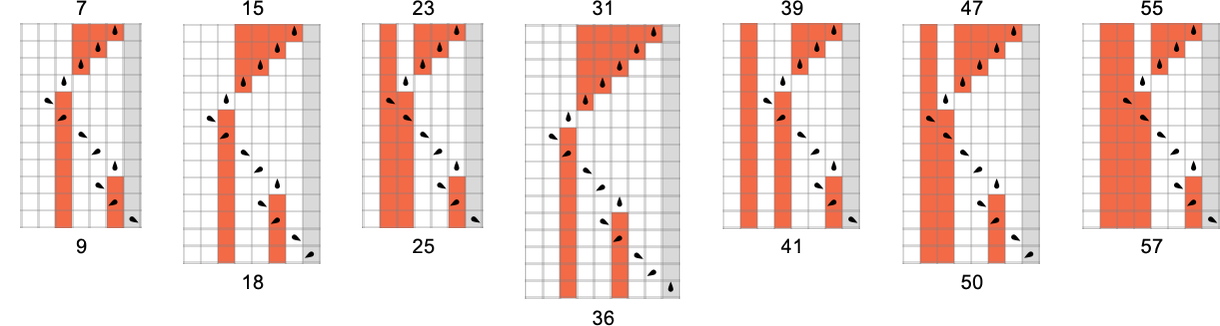
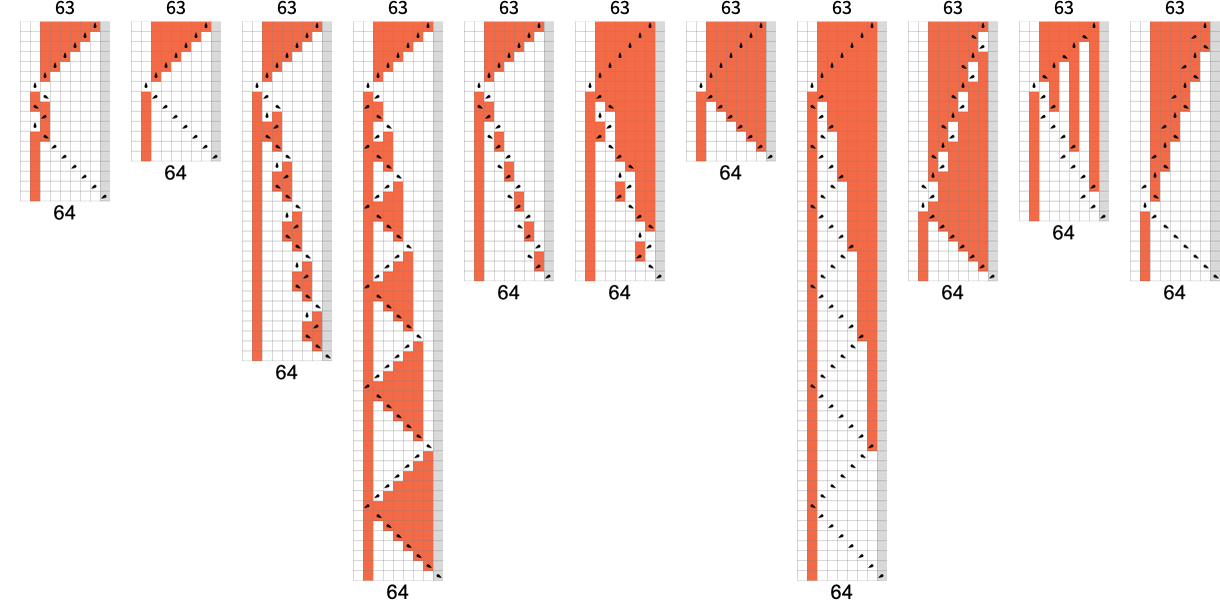
The bugs aren't random; they follow a specific ruliological pattern. They appear whenever takes the form: (Or, more simply, when ).
The magnitude of the error is determined by the formula:

Why does this happen?
- Normal Operation: The head sweeps left to handle carry bits, then sweeps right without further changes.
- Bug Operation: When the binary representation ends in
111, the head performs "extra jigs" and scribbles incorrect digits during the rightward sweep.
The Difficulty of Testing
There are exactly 8934 different 3-state, 2-color Turing machines that correctly compute . Some are straightforward, while others are complex nested structures.
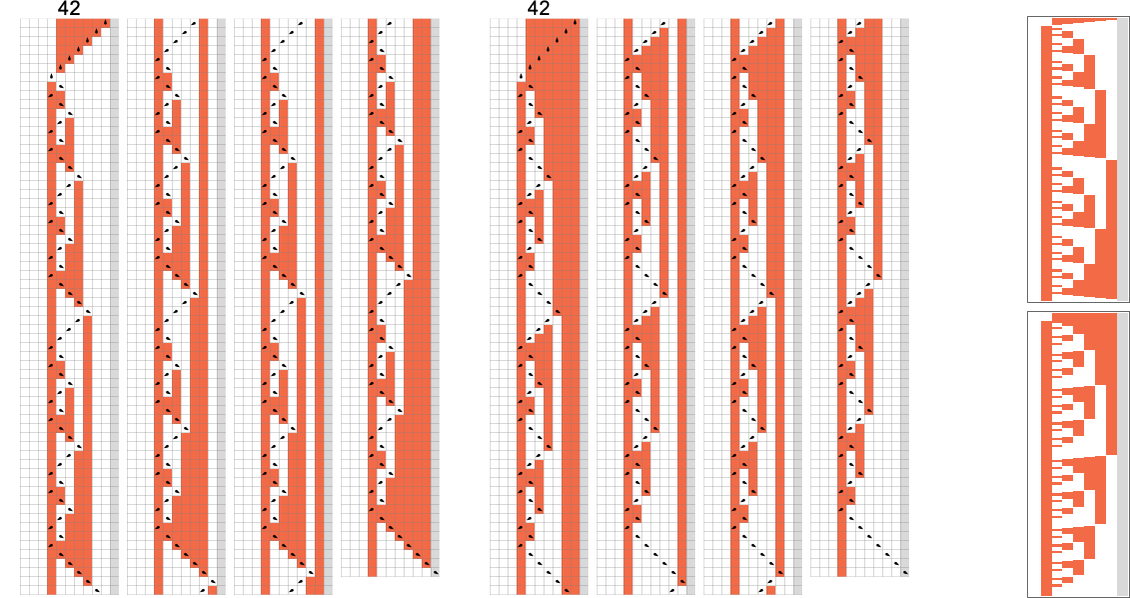
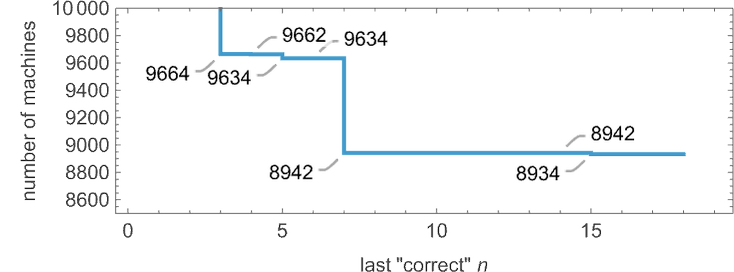
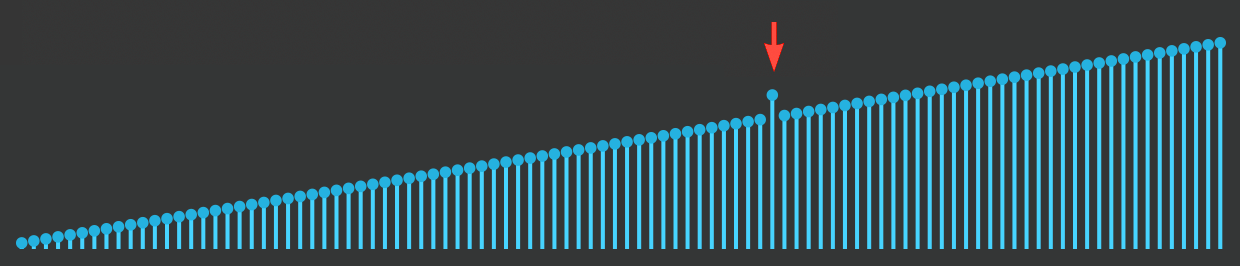
The critical takeaway is the latency of bugs. As shown in the plots of "correctness" over , some machines appear perfect for a long time before a bug finally emerges. This leads to a sobering realization about software testing:
The Tester's Dilemma
- Test small inputs.
- Test edge cases.
- Test every possible input (Impossible for irreducible systems).
If a program is computationally irreducible, you cannot know if it is "bug-free" until you have run it for every possible scenario. The "first bug" might appear at , , or .
Summary
Bugs are not just mistakes in coding; they are manifestations of computational irreducibility. When our simple mental models collide with the complex reality of a program's execution, the resulting discrepancy is what we call a bug. Understanding this helps us realize the inherent limits of software verification and the perpetual challenge of computer security.