Tailscale Traces Database Corruption to 16y/o SQLite WAL-Reset Bug
Uncovering a 16-Year-Old SQLite WAL-Reset Bug: The Tailscale Story
Published August 12, 2026
At the close of last year, Tailscale experienced a period of perfect stability shaky uptime. As reflected on our public status page, this instability persisted well into the new year. We eventually discovered that the root cause was a singular, deeply embedded bug within SQLite.
By this summer, we have successfully identified, analyzed, and resolved the issue. We recognize that our users rely on Tailscale for unwavering reliability; for several months, we fell short of that standard. This post details the failure, our response, and how we helped expose a legacy bug in one of the world's most used databases.
🏗️ Tailscale’s Database Architecture
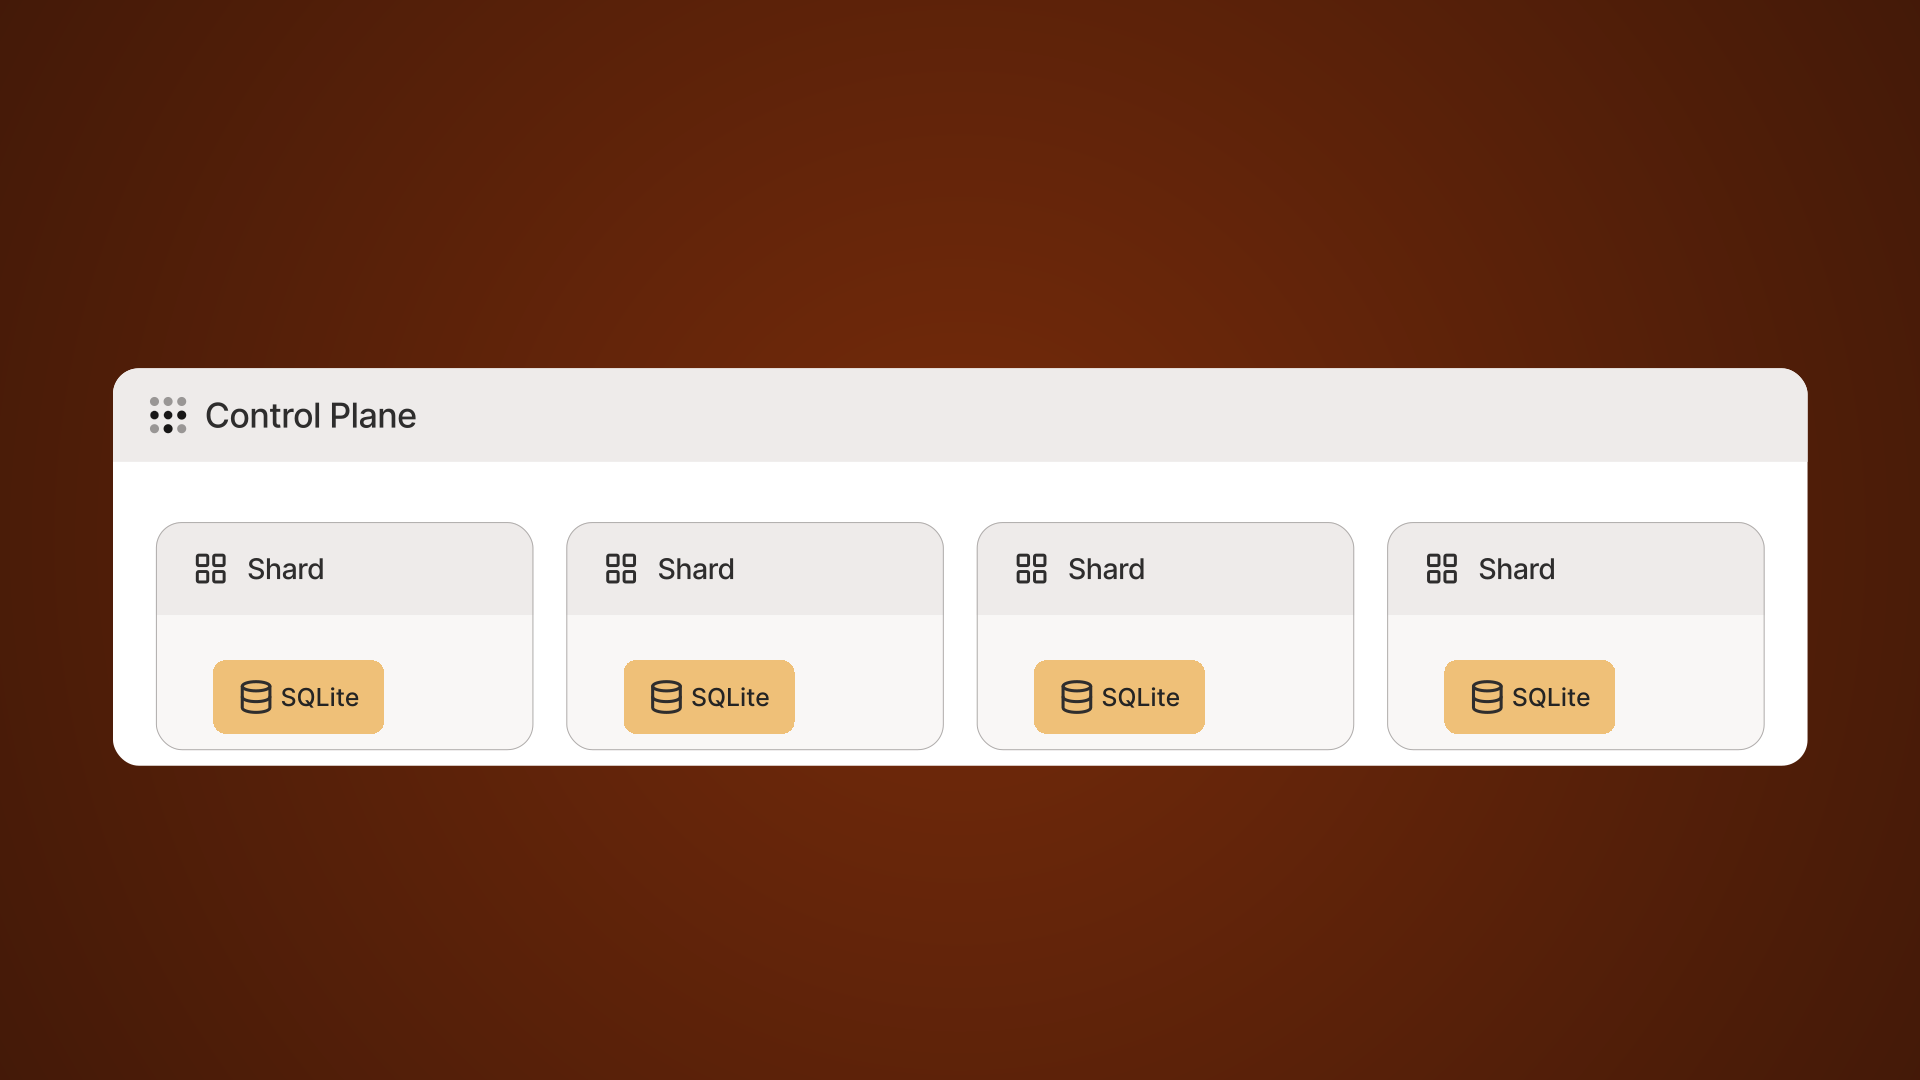
While users access our control plane via a single entry point (controlplane.tailscale.com), the backend is actually partitioned into multiple coordination servers, known as "shards."
How Sharding Works
- Distribution: Every "tailnet" is assigned to one internal shard.
- Mobility: Tailnets can migrate between shards seamlessly.
- Abstraction: This process is entirely invisible to the end user.
Each shard utilizes an SQLite database to store all relevant tailnet data. To maintain consistency, a single Go process acts as the exclusive writer for that database.
We adopted SQLite as our primary engine in 2022 due to its reputation for being reliable, well-understood, and ubiquitous. Given its success in massive deployments elsewhere, we expected a seamless experience.
The Backup Pipeline
Our reliability strategy involves a frequent snapshotting process:
- Capture a full database snapshot every few minutes.
- Upload the SQLite file to an S3 bucket.
🚨 The Discovery of Corruption
In August of last year, a data pipeline monitoring our S3 backups flagged an error. To verify, we executed the following command:
PRAGMA integrity_check;
The result confirmed our fears: the database was corrupted. While SQLite corruption is technically possible, it is an extreme rarity in standard operations. We repaired the file and searched for the cause, but found nothing.
However, at our scale, the "impossible" becomes inevitable. The corruption recurred frequently.
The Toll: Over a six-month window, we encountered distinct instances of database corruption.
Impact Analysis
It is important to clarify that "corruption" did not mean a total loss of user secrets. Because the control plane only stores configuration metadata, private encryption keys and network traffic were never at risk.
| Impact Area | Effect during Corruption |
|---|---|
| Data Loss | Minimal; some recent config changes or new devices didn't persist. |
| Availability | The shard's control plane process had to be stopped for repair. |
| Connectivity | Existing P2P WireGuard® connections remained active. |
| Onboarding | New devices could not join the network (no access to the peer list). |
| Management | Admin console and API access were temporarily unavailable. |
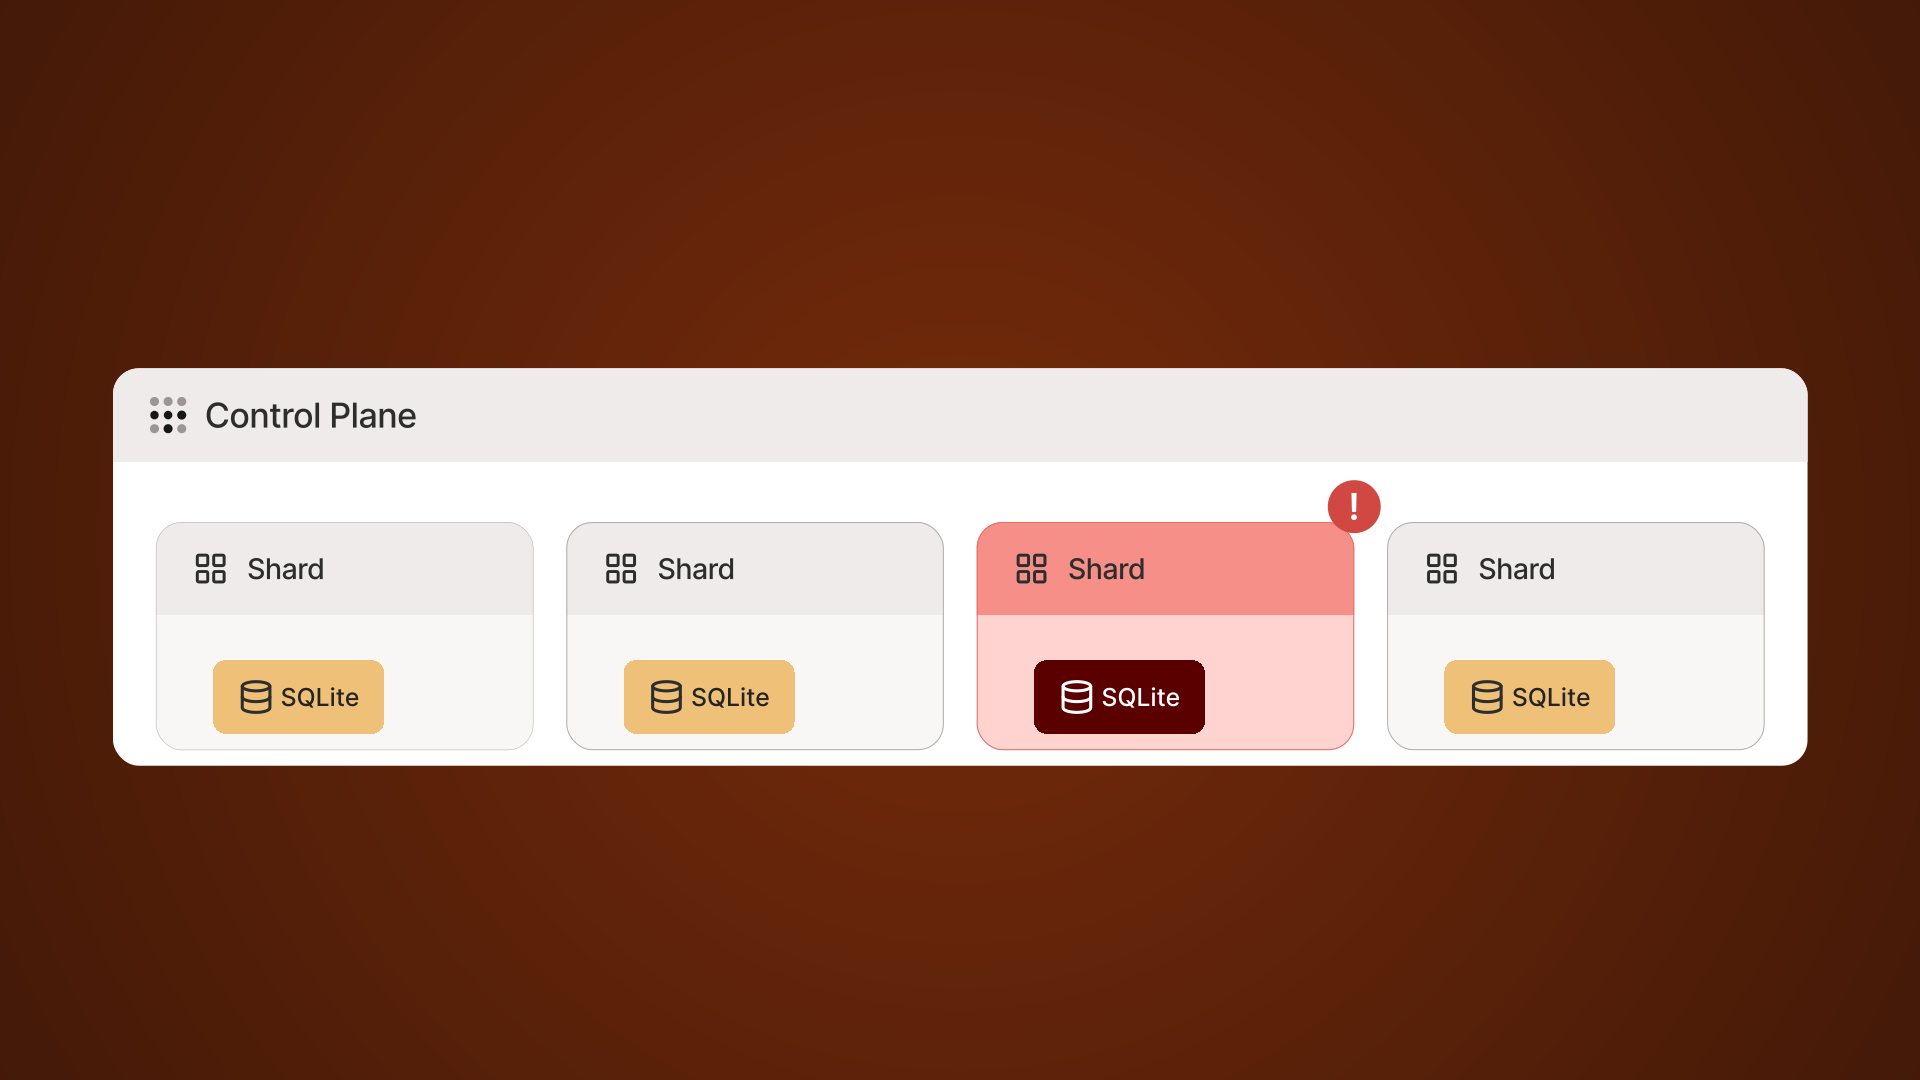
Even though most shards remained healthy, we posted global incidents on our status page. We realized that repeated downtime—even if it only affects a fraction of users—erodes overall trust.
🔍 The Hunt for the Bug
Finding the cause was an uphill battle. We began with a rigorous investigation checklist:
- Review recent code changes.
- Audit low-level SQLite interaction code (written years ago).
- Search for commonalities (specific shards, customers, or features).
- Analyze load levels and time-of-day patterns.
The result? Nothing. There was no consistent trigger, which meant we could not reproduce the bug in a synthetic environment.
Forensic Telemetry
Since we couldn't trigger the bug on demand, we had to deploy passive telemetry in production to catch the corruption in the act. This was a high-risk move, as we were essentially debugging a live database.
The process was further complicated by the irregular timing of the crashes. For example, we once faced a six-week gap between incidents, making it nearly impossible to gauge our progress.
Technical Deep Dive: WAL and Checkpoints
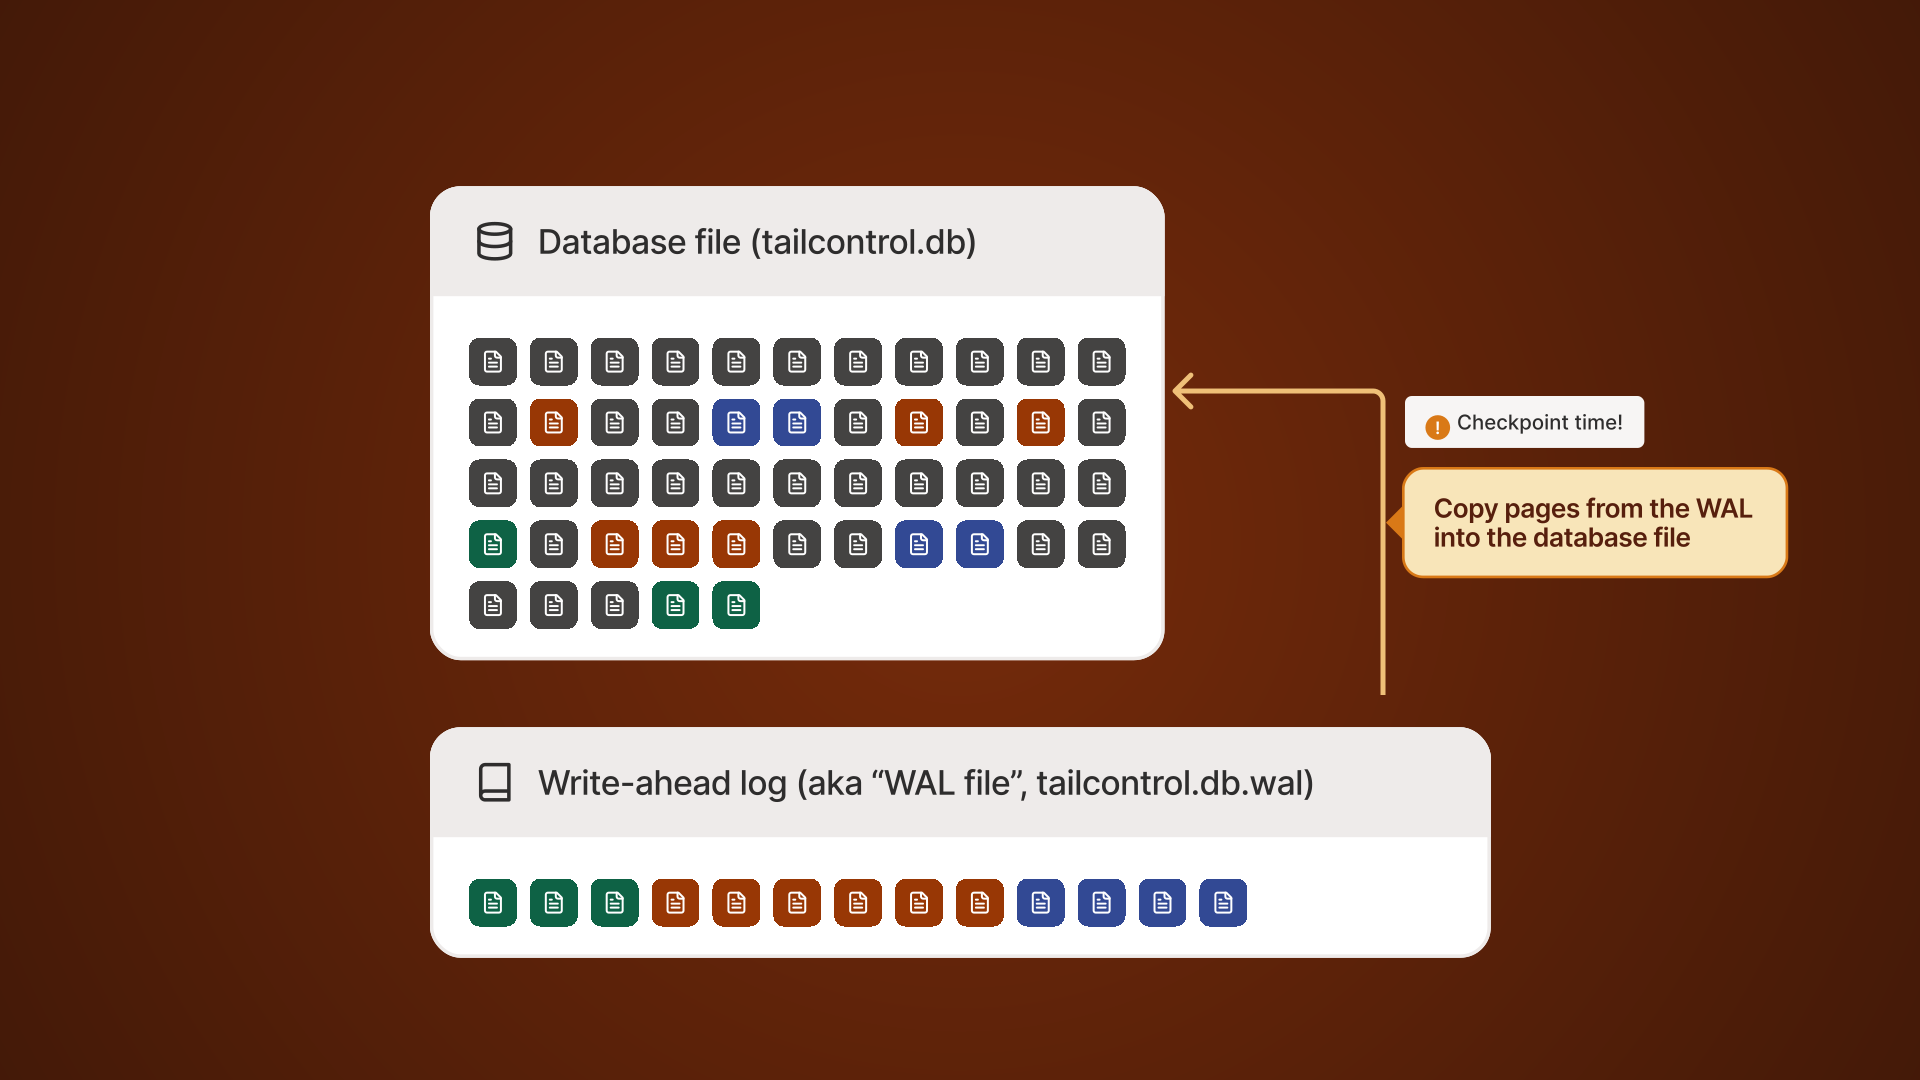
To understand the bug, one must understand the Write-Ahead Log (WAL). In SQLite, changes are written to a WAL file before being merged into the main database file during a "checkpoint."
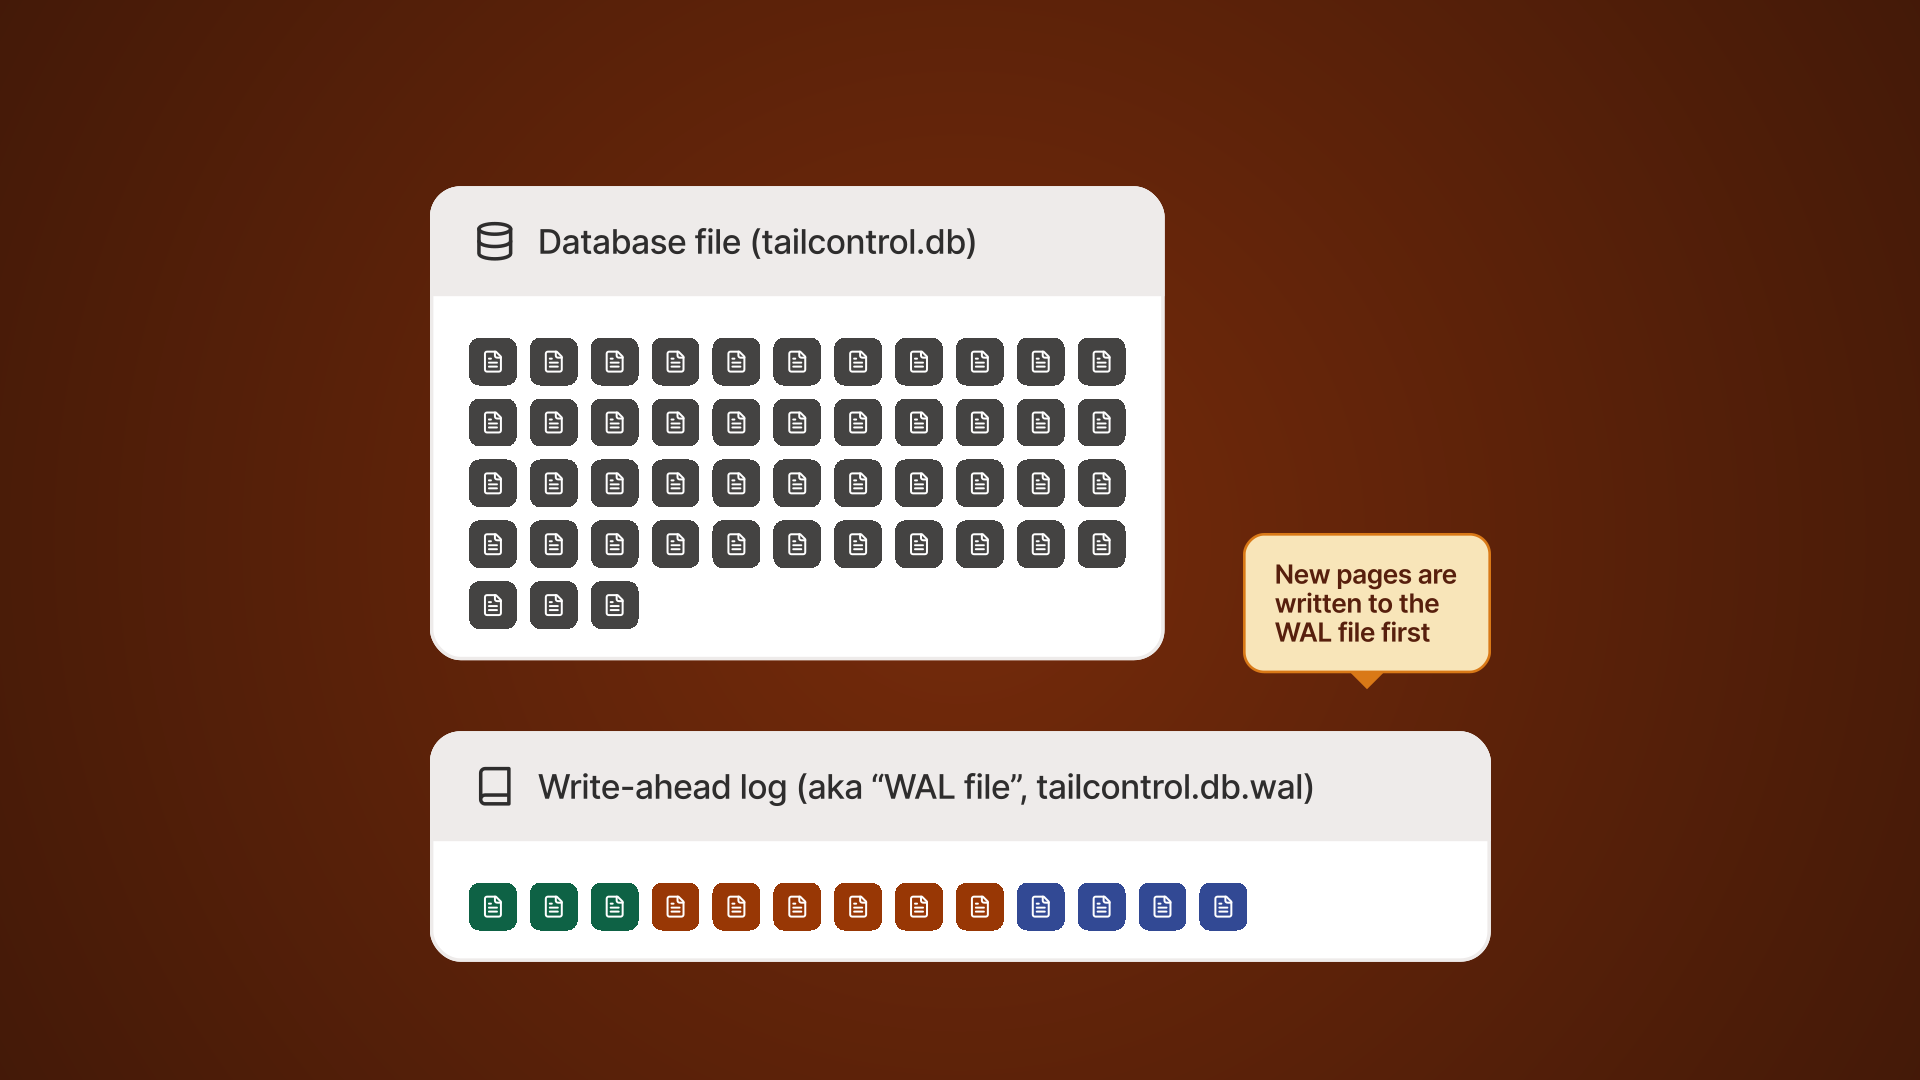
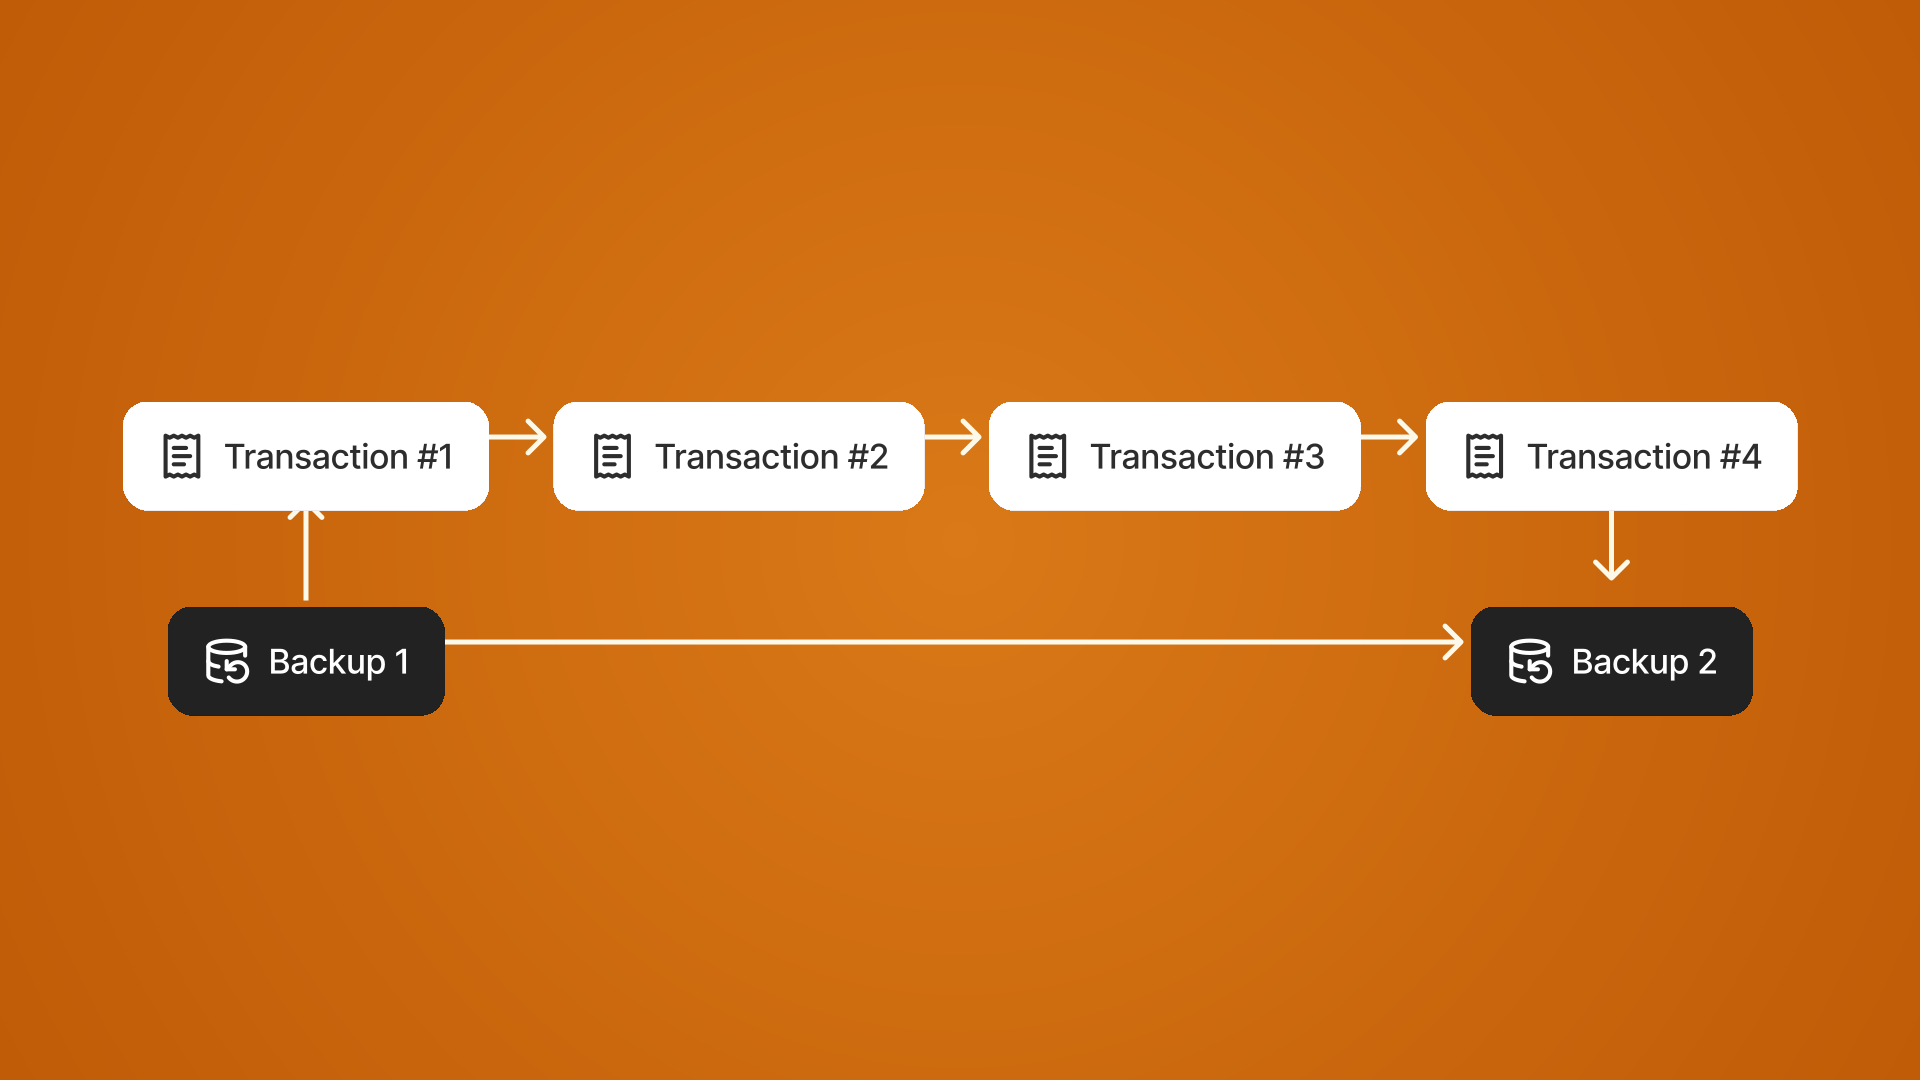
We analyzed how transactions were replayed between backups to pinpoint where the data diverged.
The Solution: tmstmpvfs
We eventually implemented a custom debugging layer. By wrapping the OS interface/virtual filesystem (VFS) in a shim called tmstmpvfs, we could track every single disk write with a timestamp.
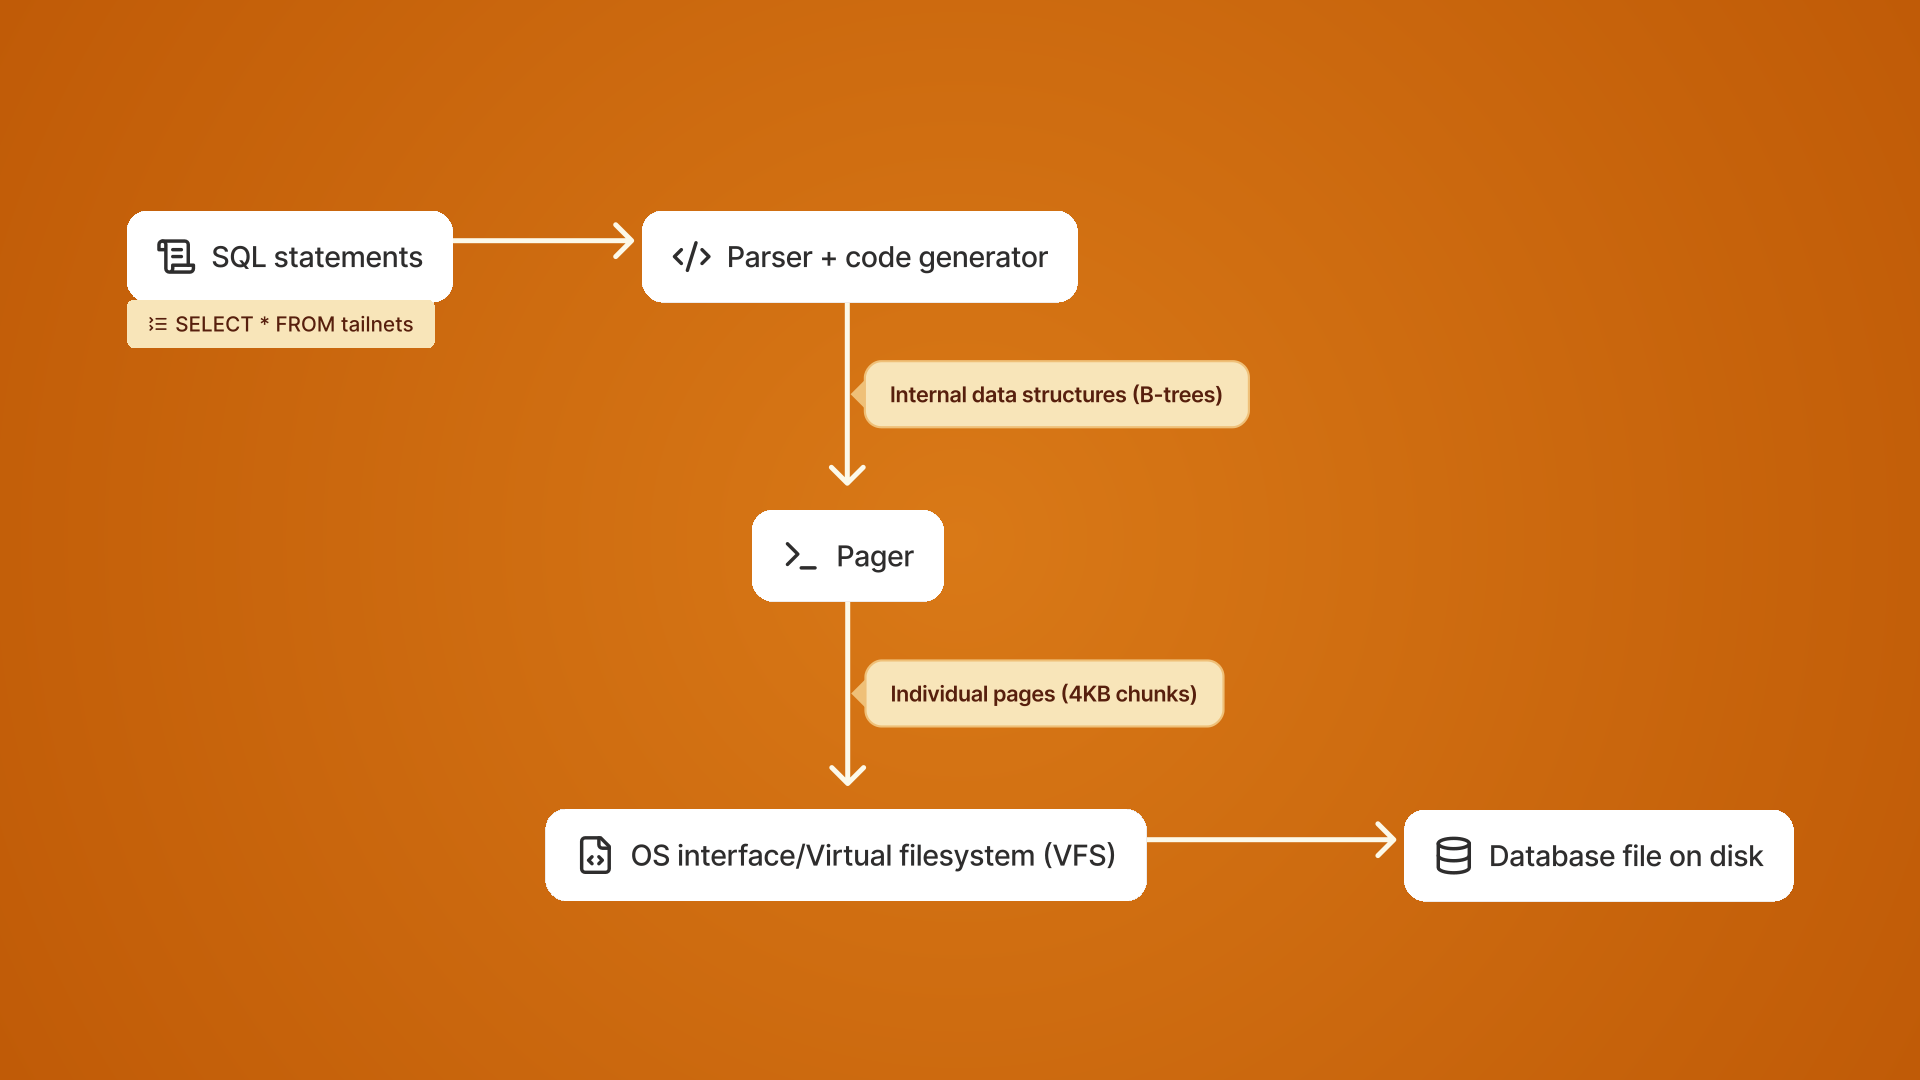
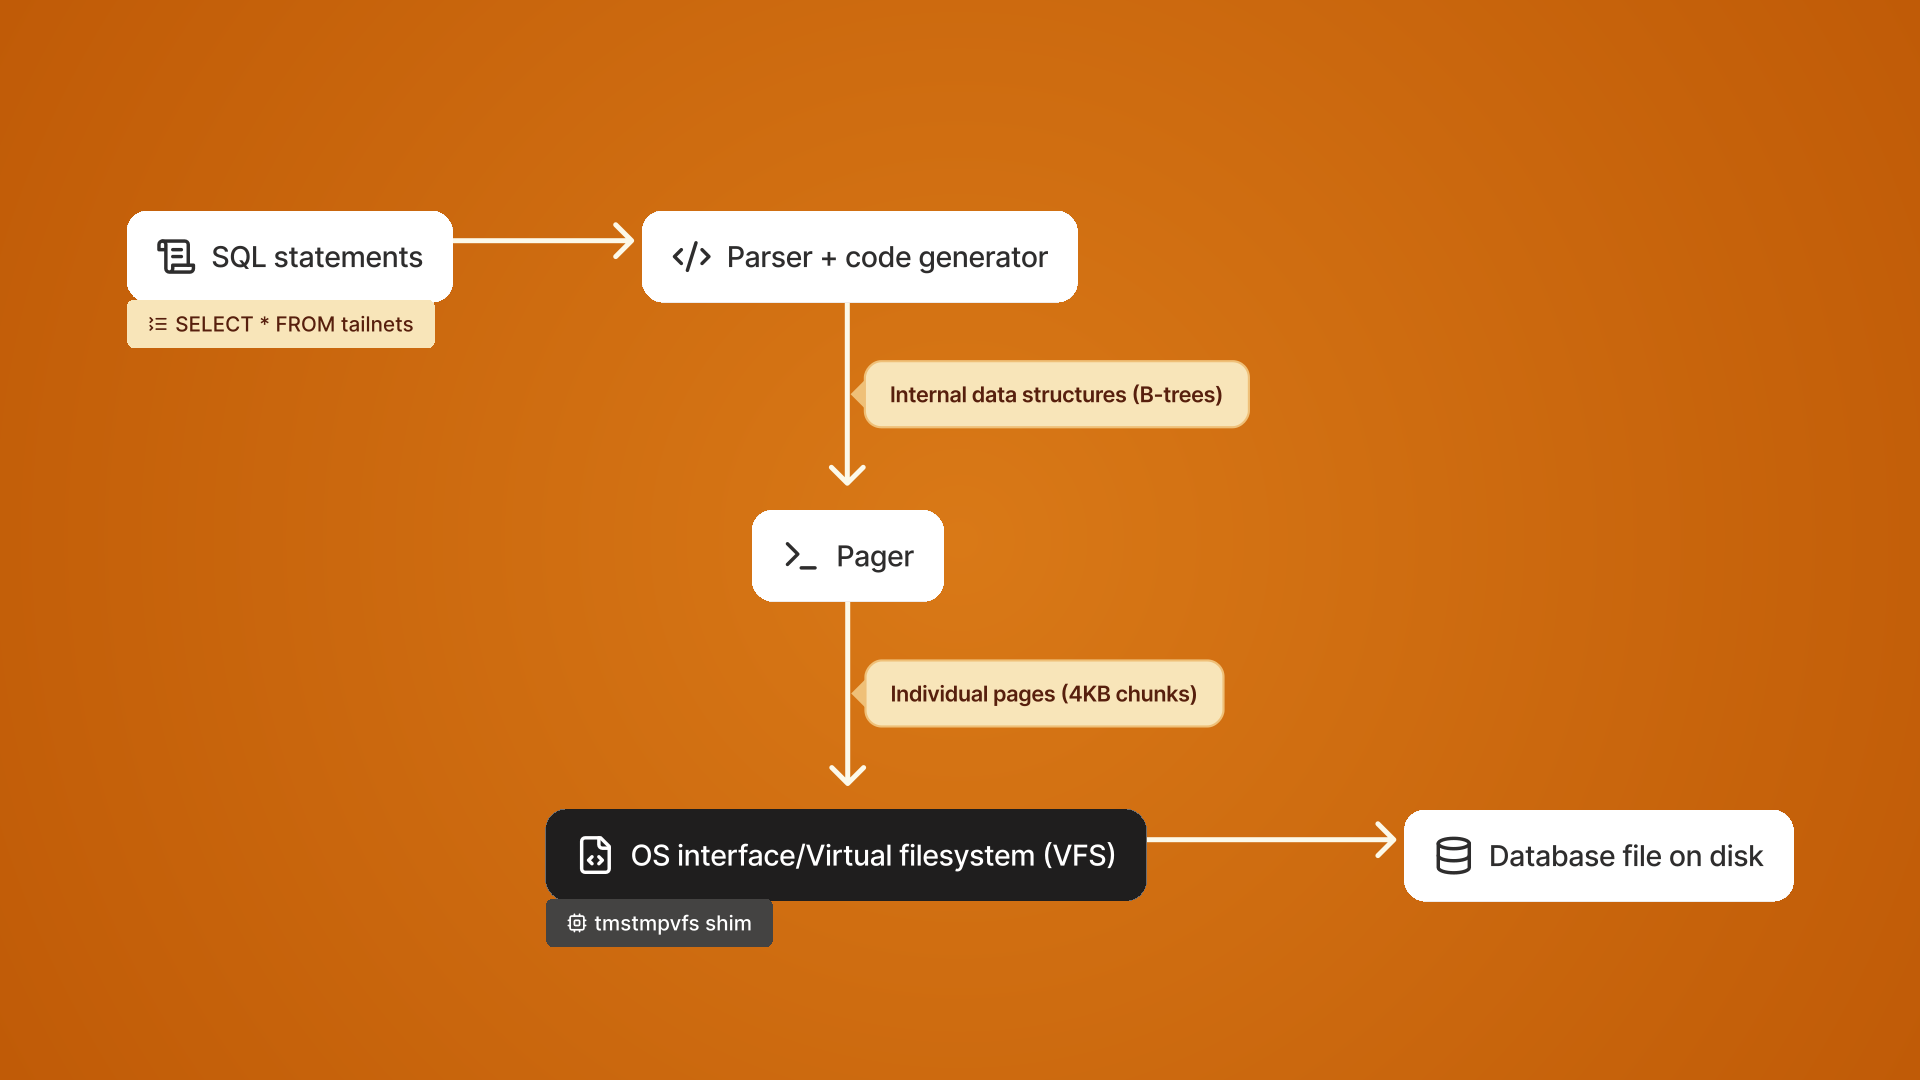
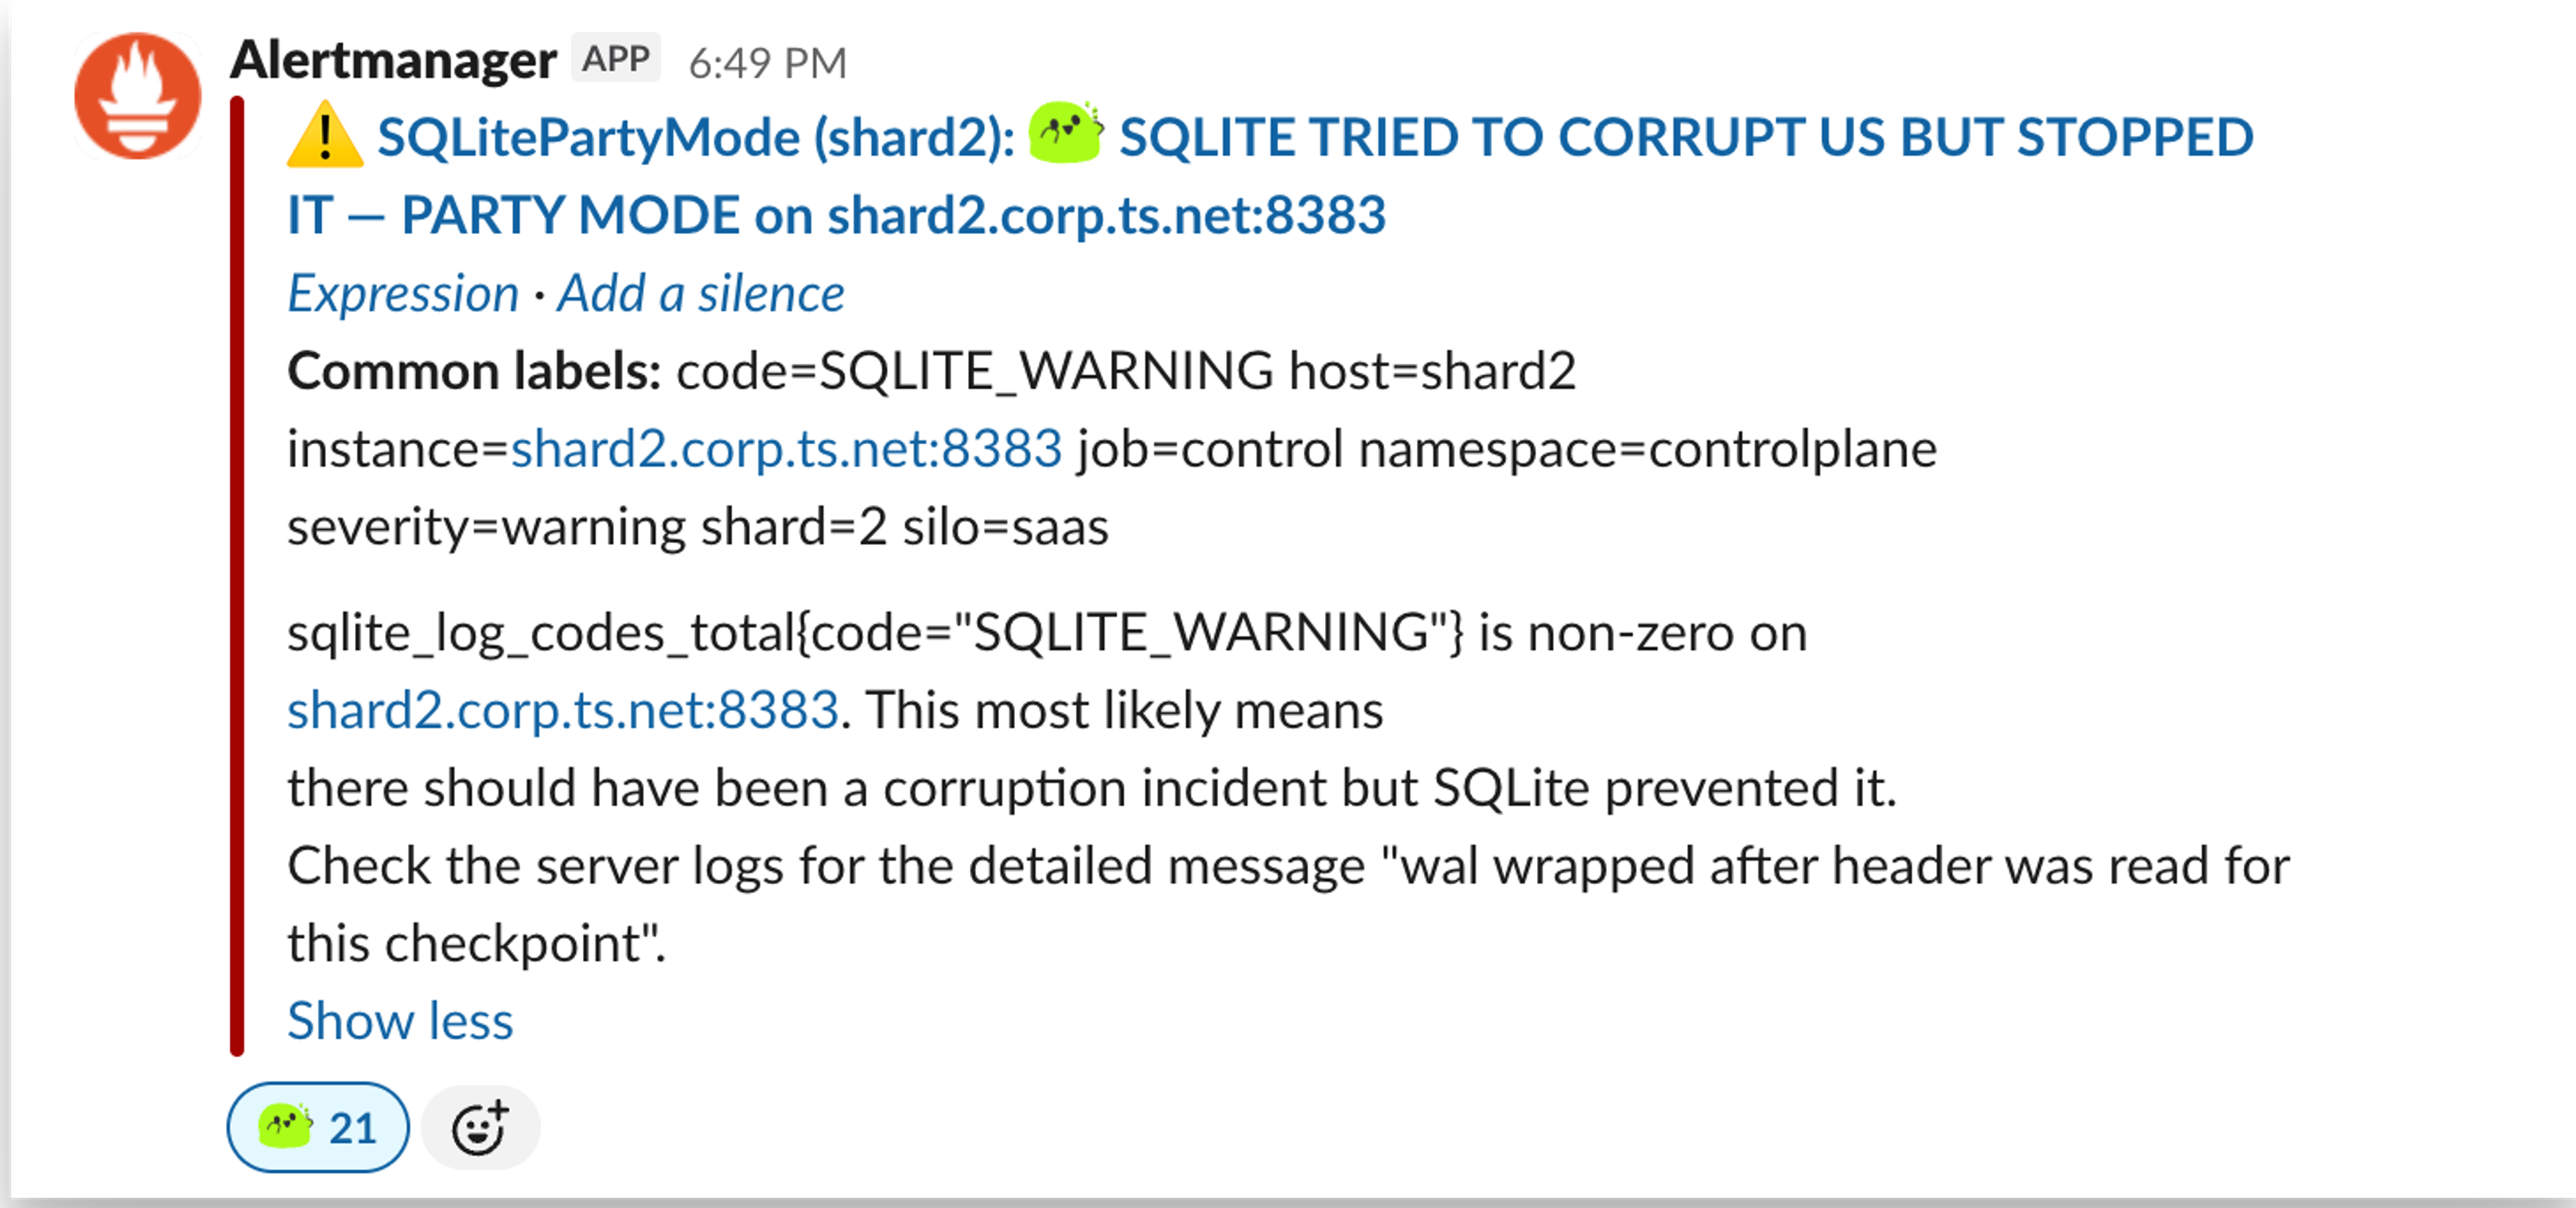
This allowed us to detect the corruption the moment it happened. We even created a "Party Mode" to alert us immediately via Alert Manager:
[WARNING] SQLitePartyMode: SQLite attempted corruption
on shard2.corp.ts.net:8383 in party mode,
but the system prevented it.
Check server logs for details.
Through this exhaustive process, we uncovered a bug related to how SQLite resets the WAL file—a flaw that had existed in the codebase for 16 years.
