SpaceXAI's Grok 4.6 Scores 61 on the Artificial Analysis Intelligence Index
SpaceXAI's Grok 4.6 Hits 61 on the Artificial Analysis Intelligence Index
Summary: With the release of
Grok 4.6, SpaceXAI has reclaimed its position at the cutting edge of AI intelligence. The model matches the capabilities of GPT-5.6 Sol while offering superior cost-efficiency and exceptional agentic performance.
Published on August 12, 2026, by Artificial Analysis.
🚀 The Return to the Frontier
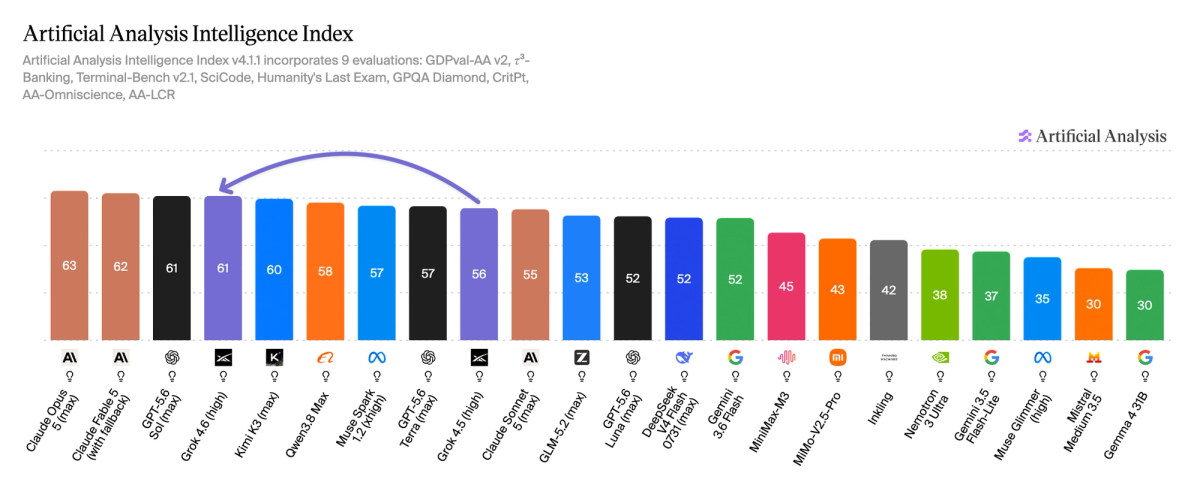
Grok 4.6 has officially joined the "intelligence frontier," scoring a 61 on the Artificial Analysis Intelligence Index. This represents a significant leap in capability:
Grok 4.3+23 pointsGrok 4.5+5 points (achieved in just over a month)
This surge places SpaceXAI back in the top tier alongside OpenAI, trailing only Anthropic's latest offerings.
📌 Key Takeaways
- Frontier Status: Scores 61, tying with
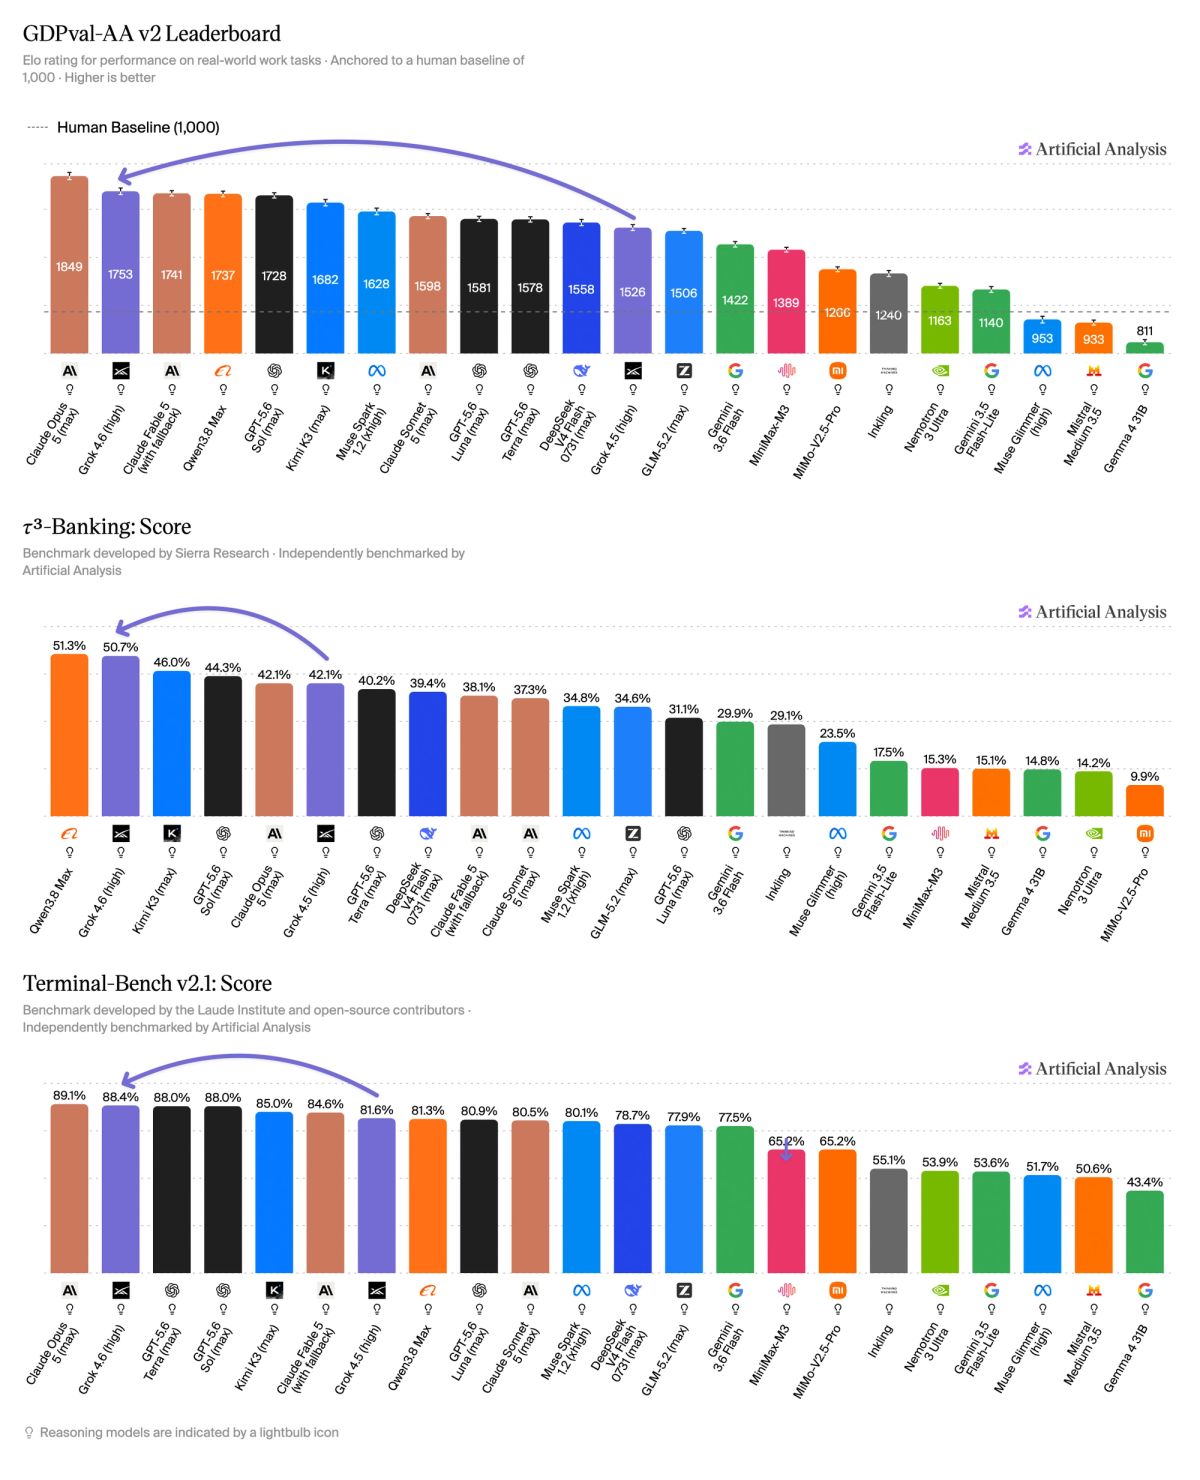
GPT-5.6 Sol (max). - Agentic Power: High GDPval-AA v2 Elo (1753), rivaling the best in the industry.
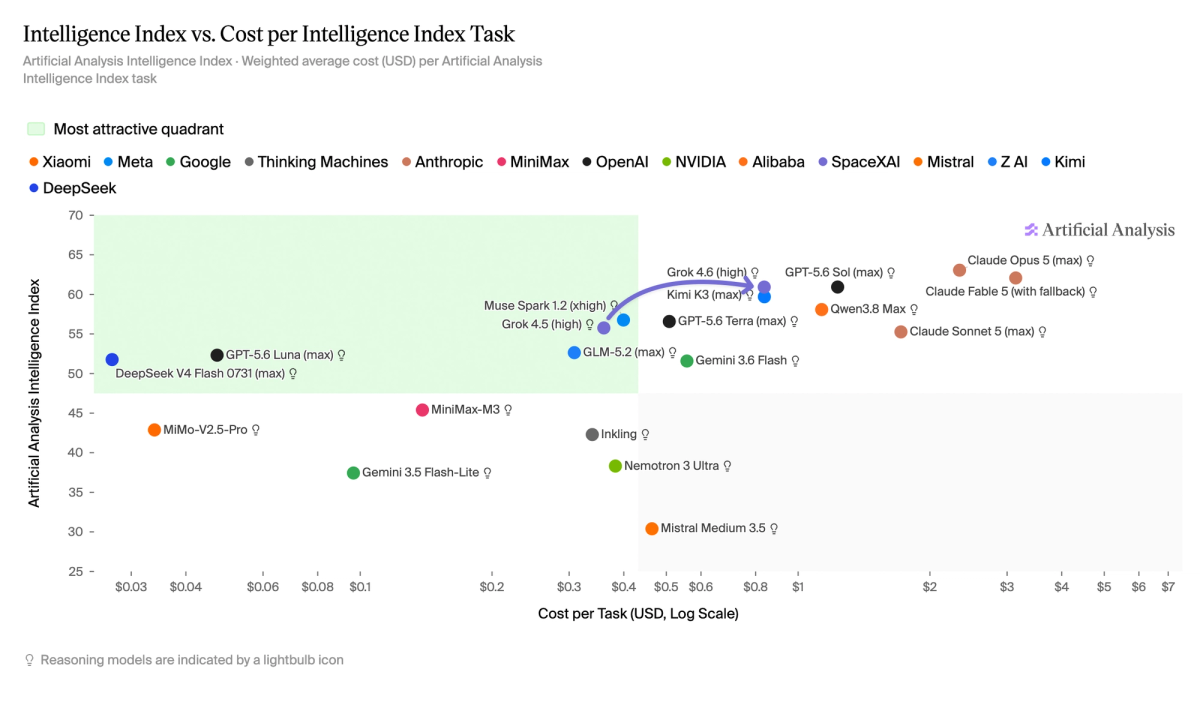
- Price Leadership: Maintains
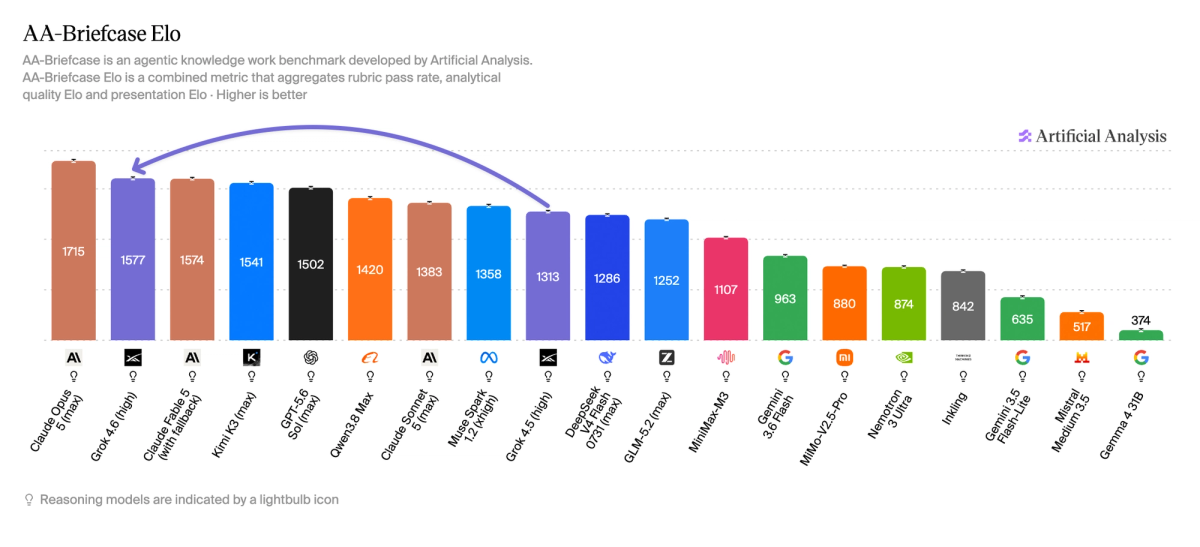
Grok 4.5pricing, significantly undercutting competitors. - Efficiency: High turn-efficiency in long-horizon tasks via the AA-Briefcase benchmark.
📊 Intelligence & Performance Metrics
Intelligence Index Standings
The following table illustrates where Grok 4.6 sits relative to its primary competitors:
| Model | Intelligence Index Score | Status |
|---|---|---|
| Claude Opus 5 (max) | 63 | Leader |
| Claude Fable 5 (max w/ fallback) | 62 | Frontier |
| Grok 4.6 | 61 | Frontier |
| GPT-5.6 Sol (max) | 61 | Frontier |
| Kimi K3 | < 61 | Near-Frontier |
Agentic Capabilities
Grok 4.6 excels specifically in agentic workflows rather than just static reasoning.
Key Benchmarks:
- GDPval-AA v2: Achieved an Elo of
1753. It is statistically indistinguishable fromClaude Fable 5andQwen3.8 Max, trailing onlyClaude Opus 5. - -Banking: Scored 50.7% (Testing multi-turn tool use for customer service), placing it in the top two alongside
Qwen3.8 Max(51.3%). - Terminal-Bench v2.1: Scored 88.4%, matching the industry leaders in terminal-based software engineering tasks.
💰 Cost Efficiency & Value
SpaceXAI has taken the unusual step of keeping headline pricing flat despite the intelligence gains.
Pricing Comparison (per 1M tokens)
| Model | Input Price | Output Price |
|---|---|---|
Grok 4.6 | $2 | $6 |
Claude Opus 5 | $5 | $25 |
GPT-5.6 Sol | $5 | $30 |
Additional Financial Details:
- Cache Hits: Now priced at
$0.5per 1M tokens (an increase from the$0.3seen inGrok 4.5). - Cost per Task: Measured at
$0.84, identical toKimi K3.
Because output tokens dominate the cost of reasoning-heavy workloads, Grok 4.6 provides a massive financial advantage over GPT-5.6 Sol while delivering equivalent intelligence.
# Hypothetical Cost Comparison for a Reasoning Task
def calculate_cost(input_tokens, output_tokens, input_rate, output_rate):
    return (input_tokens * input_rate / 1e6) + (output_tokens * output_rate / 1e6)

# Grok 4.6 vs GPT-5.6 Sol (Example: 10k input, 5k output)
grok_cost = calculate_cost(10000, 5000, 2, 6) # $0.05
gpt_cost = calculate_cost(10000, 5000, 5, 30) # $0.20
print(f"Grok is {gpt_cost/grok_cost:.1f}x cheaper in this scenario.")
💼 Long-Horizon Knowledge Work
Using the private AA-Briefcase benchmark, Grok 4.6 debuted with an Elo of 1577, placing it in the Fable 5-tier. It shows balanced strength across analytical quality, presentation, and rubric grading.
Efficiency Breakdown: Grok 4.6 vs. Claude Opus 5 (max)
- Turn Efficiency:
Grok 4.6completes tasks in turns, whereasOpus 5requires turns. - Token Consumption:
Grok 4.6uses input tokens on average, compared to forOpus 5.
This means Grok 4.6 is not only cheaper per token but reaches the correct answer using significantly fewer resources.
🛠️ Technical Specifications & Other News
Model Specs:
- Context Window:
500ktokens (No change from 4.5).
Other Industry Updates
- Upstage Solar Pro 4: Released August 12, 2026.
- NVIDIA Nemotron 3.5 Lightning: Launched August 11, 2026, focusing on on-device intelligence.
- AA-AnalystAgent: A new benchmark for quantitative analysis using real-world spreadsheets.
- Tests 80 private questions across 14 domains.
- Primary Metric: (must solve the problem on all 5 attempts to be considered successful).
Visual Gallery
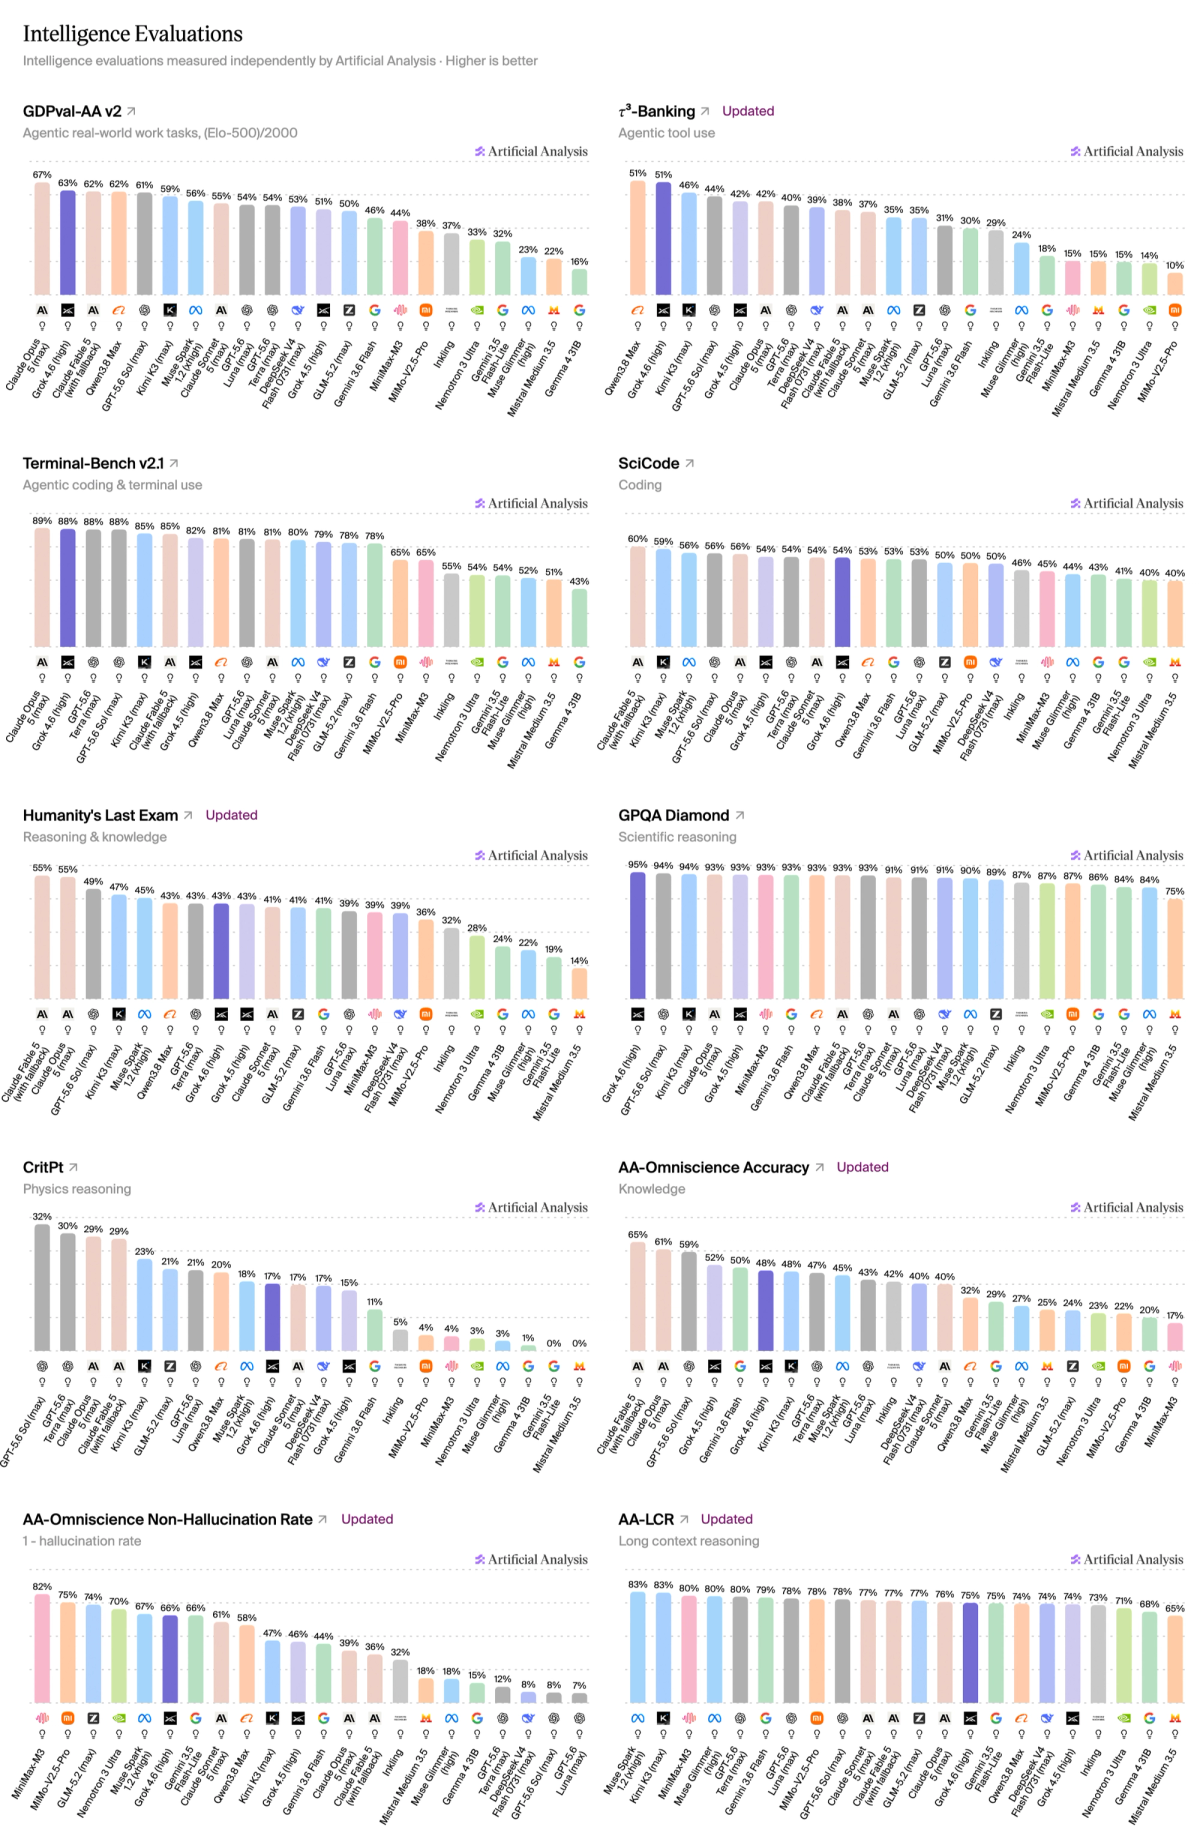


For a full breakdown of evaluations, visit Artificial Analysis.