Project HydraFusion: Frontier quality via multi-model orchestration
Project HydraFusion: Achieving Frontier-Level Quality through Multi-Model Orchestration
Summary: In controlled offline tests, HydraFusion's selective coding workflows matched or surpassed the Opus 5 baseline while significantly lowering the estimated cost of the workflow.
Published by GitHub Staff on September 4, 2026
GitHub's primary objective has always been to ensure developers have access to the most effective model for any given task. Earlier this year, we streamlined this process with Auto model selection, which analyzes a task and pairs it with the most appropriate model.
Today, we are unveiling Project HydraFusion, a research preview designed to provide "frontier intelligence" via runtime orchestration. Instead of relying on a single LLM, HydraFusion constructs a comprehensive execution strategy, utilizing a variety of models from different providers to draft, critique, revise, or escalate tasks to more powerful systems.
HydraFusion is a cornerstone of our broader strategy to implement automated semantic routing across manual local, cloud, and compound model architectures. For the end-user, this complexity is abstracted away: you simply select HydraFusion as your model, and the system autonomously optimizes for performance, cost, and latency.
🚀 Getting Started with the Research Preview
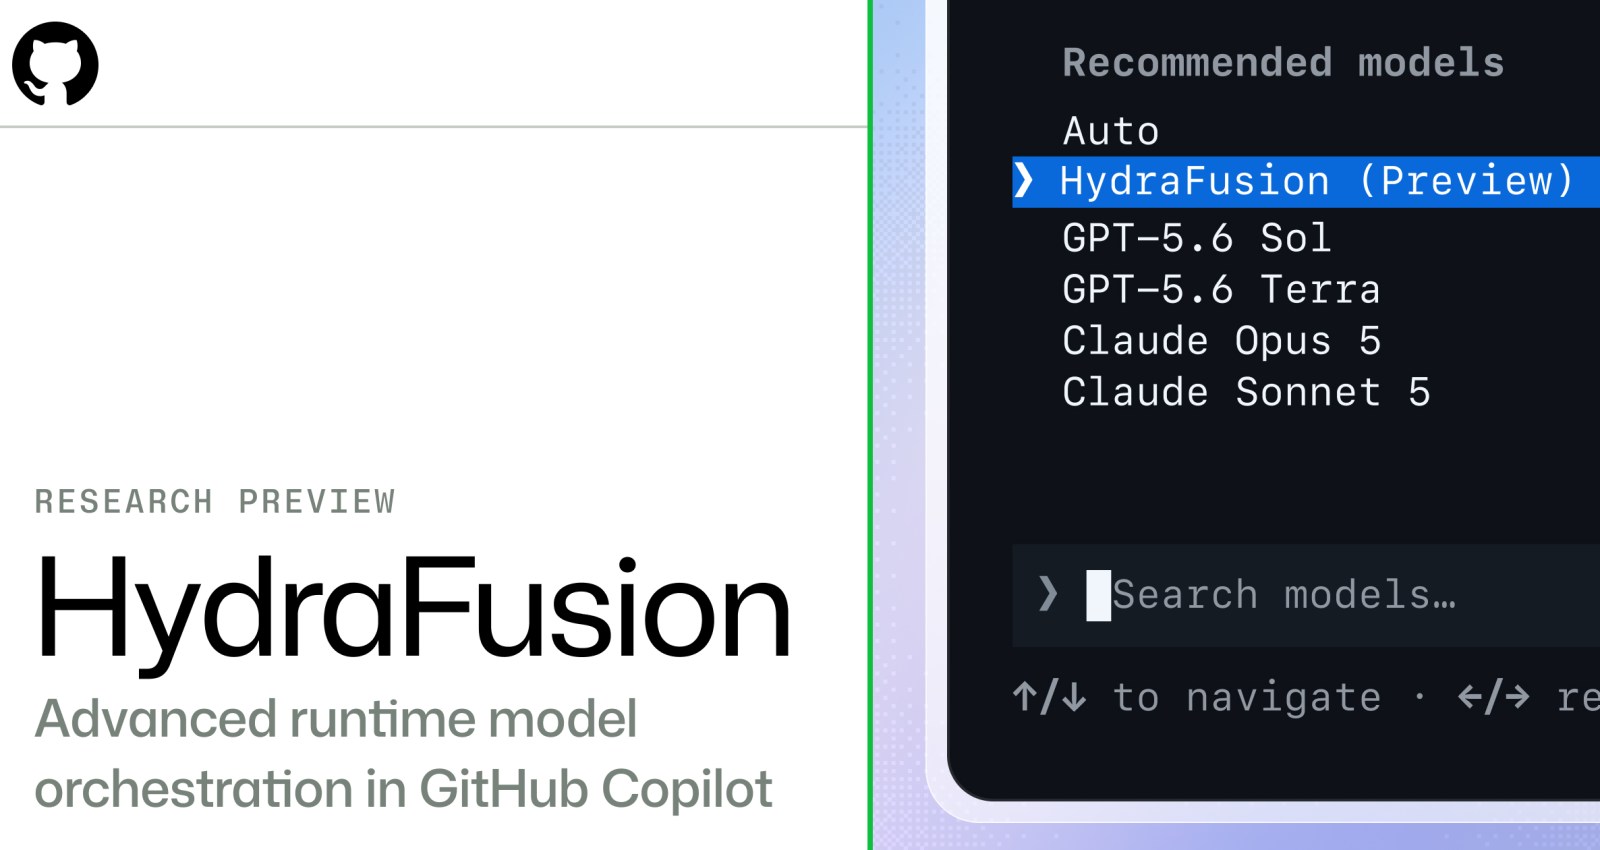
HydraFusion is currently available to all GitHub Copilot subscribers via the /experimental flag in the GitHub Copilot CLI.
Pricing Note: Costs are calculated based on the standard token rates of the specific models invoked by the HydraFusion orchestrator.
Installation Steps
- Update your CLI to the latest version.
- Enter the experimental mode.
- Select the HydraFusion model.
# Step-by-step CLI execution
/update
/experimental
/model # Then select "HydraFusion (Research Preview)"
We encourage users to share their experiences in the GitHub Community.
🧠 The Logic of Orchestration
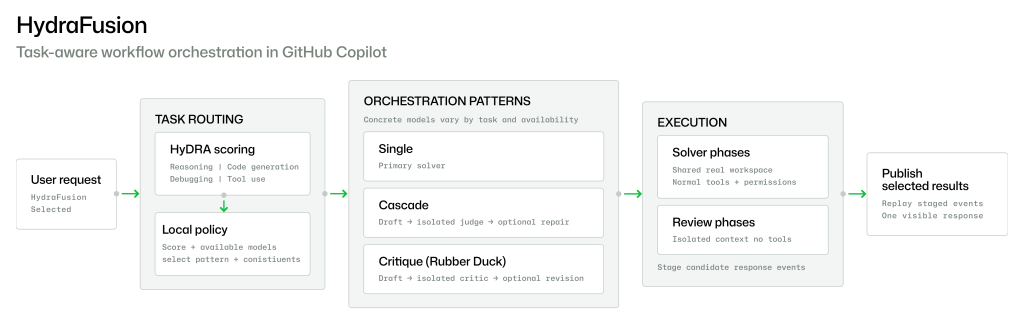
HydraFusion treats the selection of a workflow as a mathematical optimization problem. By analyzing "capability signals"—such as the need for complex reasoning, specific code generation, debugging, or tool interaction—it determines the most efficient path to reach a high-quality result.
Execution Patterns
Currently, HydraFusion utilizes three primary patterns:
| Pattern | Logic | Primary Goal |
|---|---|---|
| Single | A fast model drafts a quality gate checks the result accept or escalate. | Speed & Efficiency |
| Cascade | An efficient model attempts the task if it fails the gate, a stronger model takes over. | Balanced Cost/Quality |
| Critique | Model A drafts an independent Model B (different family) reviews Model A revises. | High Precision/Accuracy |
📊 Performance and Benchmarks
In offline evaluations across three agentic coding benchmarks—TerminalBench 2.1, DeepSWE, and Ch—HydraFusion consistently delivered frontier-level quality while slashing costs.
For example, on TerminalBench 2.1, the results were: (Compared to the Claude Opus 5 baseline)
🛠️ Engineering the Experience
Moving from manual model switching to automated orchestration requires rigorous control. HydraFusion is governed by five core operating principles:
- Comprehensive Accounting: Every "leg" of the workflow (drafting, critique, etc.) is tracked for cost and usage.
- Strict Constraints: Each step has explicit
timeoutandcancellationbehaviors to prevent runaway costs. - Contextual Isolation: Review steps are performed in read-only, tool-less environments. This ensures critics can evaluate work without accidentally altering the codebase.
- Atomic Application: No patches are applied if a workflow is cancelled or fails validation, ensuring the repository remains in a clean state.
- Pre-flight Verification: The system verifies model availability and binding definitions before the execution begins.
The Developer Interface
Currently, HydraFusion displays the active workflow stage but hides intermediate drafts.
The Reasoning: Since drafts are often revised or discarded, showing them in real-time could mislead developers into thinking an unfinished thought is the final solution. However, we recognize that "blind waiting" is a friction point and are exploring more transparent progress updates.

Additional Resources