Gemini 3.8 text-to-speech
Gemini 3.8 Text-to-Speech: A New Era of Audio Expression
Date: September 23, 2026
Authors: Leland Rechis (Group Product Manager) and Alan Cowen (Director, Research Science), representing the Gemini Audio Team.
Google has officially unveiled Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, marking a significant leap in the expressiveness of AI-generated audio. These tools transition voice synthesis from static, pre-set options into a fully dynamic creative studio.
🎙️ Overview of the New Models
The latest additions to the Gemini Audio family allow developers and creators to design bespoke character voices and orchestrate complex dialogue. These models are integrated across several platforms:
- Google AI Studio & Gemini API
- Gemini Enterprise
- Gemini Notebook
- Google Vids
Model Comparison
| Feature | Gemini 3.8 Flash TTS | Gemini 3.8 Flash-Lite TTS |
|---|---|---|
| Primary Focus | Deep creative direction & character design | High-volume, cost-efficient scaling |
| Best Use Case | Gaming, immersive audiobooks, podcasts | Dubbing, voice agents, mass content |
| Control Level | Granular (acting cues, dialect shifts) | Fine-grained (tone, pacing, nuance) |
| Capability | Bespoke voice creation from scratch | Optimized for speed and efficiency |
🛠️ Key Capabilities & Innovation
The power of these models lies in their ability to interpret natural language prompts to shape audio.
1. Generative Voice Design
Users are no longer limited to a handful of presets. You can now scale from a small set of voices to an unlimited library:
By using natural language, you can define the role, accent, and specific characteristics of a voice across more than 100 different languages and dialects.
2. Precise Performance Direction
You can now direct audio on a line-by-line basis. This includes:
- Pacing: Controlling the speed and rhythm of speech.
- Emotion: Injecting specific feelings into the delivery.
- Conversational Realism: Adding "backchanneling" (like "mm-hmm" or "yeah") and other realistic human sounds.
3. The Audio Ecosystem
These models build upon the existing Gemini Audio foundation, joining a lineage that includes:
3.5 Live Translate3.5 Transcribe3.8 Live3.8 Live Extended Thinking
📉 Performance & Validation
Google has benchmarked these models against industry standards to ensure top-tier quality.


Workflow Logic
🛡️ Safety and Responsibility
To ensure these powerful tools are used ethically, Google has implemented rigorous safety measures.
"We’ve included built-in safety tools like watermarking to keep your generated audio secure."
This prevents the misuse of synthetic voices and ensures that AI-generated content can be identified.
🌟 Industry Feedback
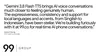
Various leaders are already integrating these capabilities into their workflows:

🚀 Getting Started
If you are a developer looking to implement these models, here is a conceptual example of how a prompt might look in the Gemini API:
{
  "model": "gemini-3.8-flash-tts",
  "input_text": "Welcome to the futuristic city of Neo-Tokyo!",
  "voice_design": {
    "description": "A weathered, gravelly voice of an old detective, slight Japanese accent, tired but authoritative tone",
    "emotion": "melancholy",
    "pacing": "slow"
  }
}
Implementation Checklist
- Access Google AI Studio
- Select
Gemini 3.8 Flash TTSorFlash-Lite - Define character persona via natural language
- Apply line-by-line emotional cues
- Verify audio watermarking for safety compliance