Retrofitting language models to operate over bytes
Retrofitting Language Models to Operate Over Bytes
Executive Summary
Recent breakthroughs in artificial intelligence have been primarily propelled by Large Language Models (LLMs)—deep neural architectures that process information via discrete units known as tokens. Traditionally, these models rely on subword tokenization, which groups characters into word fragments. While effective for general text, this approach masks granular details essential for specialized data, such as biological sequences or computer programming code.
To address this, researchers have proposed models that operate directly on UTF-8 byte encodings. However, these byte-level models have historically underperformed compared to their subword counterparts. This paper introduces "byteification," a novel two-stage retrofitting process that converts existing subword-based LLMs into byte-level models. This method allows byte-level systems to approach the performance of state-of-the-art subword models while maintaining high inference speeds and leveraging existing LLM ecosystems.
The Tokenization Dilemma
While modern AI emphasizes end-to-end learning, LLMs are not truly end-to-end. There is a critical preprocessing step where raw text is mapped to tokens:
The Pitfalls of Subword Tokenization
Most contemporary LLMs utilize subword tokenization, which introduces several systemic vulnerabilities:
- Loss of Granularity: It obscures character-level information, hindering the model's ability to handle:
- 💻 Computer Code: Where a single character (like a semicolon) changes logic.
- 🧬 Biological Sequences: Where individual nucleotides are the primary unit of meaning.
- Implicit Bias: The way a prompt is tokenized can skew the model's generated responses.
- Linguistic Hegemony: Fixed vocabulary sizes often lead to an English-centric bias, as other languages are fragmented less efficiently.
- Computational Inefficiency: Compute resources may be allocated suboptimally across tokens.
Comparison: Subword vs. Byte-Level Processing
| Feature | Subword Tokenization | Byte-Level Processing |
|---|---|---|
| Unit of Analysis | Word fragments | Raw UTF-8 bytes |
| Granularity | Coarse | Fine-grained |
| Vocab Size | Large (thousands of tokens) | Small (fixed at 256 bytes) |
| Domain Strength | General natural language | Code, DNA, Multilingual text |
| Current Status | Industry Standard | Historically lagging in performance |
The Performance Gap
There is a notable discrepancy between the theoretical potential of byte-level models and their practical adoption.
The Hypothesis: The failure of byte-level models to achieve widespread use stems from the fact that they are typically trained from
random initialization.
Because subword-based LLMs evolve rapidly—benefiting from sophisticated data curation, architectural tweaks, and post-training—byte-level models starting from scratch cannot keep pace without massive, redundant investment.
The Solution: Byteification
Instead of starting from zero, the authors propose retrofitting. By taking a pre-trained subword model and converting it, they bypass the need for an exhaustive initial training phase.
Key Outcomes and Advantages
The resulting retrofitted models demonstrate that raw text encodings can scale competitively. The primary achievements include:
- Performance Parity: Approaches the capabilities of state-of-the-art subword systems.
- Superior Reasoning: Excels in tasks requiring character-level precision.
- Efficiency: Maintains practical inference speeds despite the increased sequence length of bytes.
- Ecosystem Compatibility: Reuses the existing infrastructure and tools designed for the original source LLM.
Visual References
The research incorporates various architectural analyses, as seen in the following conceptual figures:

Figure 1: Conceptual mapping of the byteification transition.
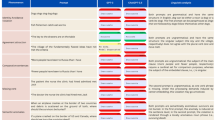
Figure 2: Comparison of tokenization densities.
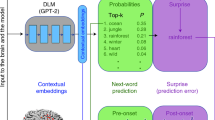
Figure 3: Placeholder for performance scaling metrics.
Conclusion
By removing the performance barrier associated with byte-level modeling, this research proves that models operating on raw encodings are not only viable but advantageous for domains requiring deep, fine-grained textual understanding.